An AI agent will do in seconds what used to take an afternoon. It will also, given the chance, do the wrong thing in seconds; and hand it back with the same confidence as the right thing. The speed is real. So is the risk, and most teams are pricing only the first one.
The reflex is to make the model better: a sharper prompt, a bigger model, more guardrails bolted onto the output.
That treats the agent as the thing to fix. But the agent isn’t the problem. The problem is what it’s standing on.
A confident answer is not a checked answer
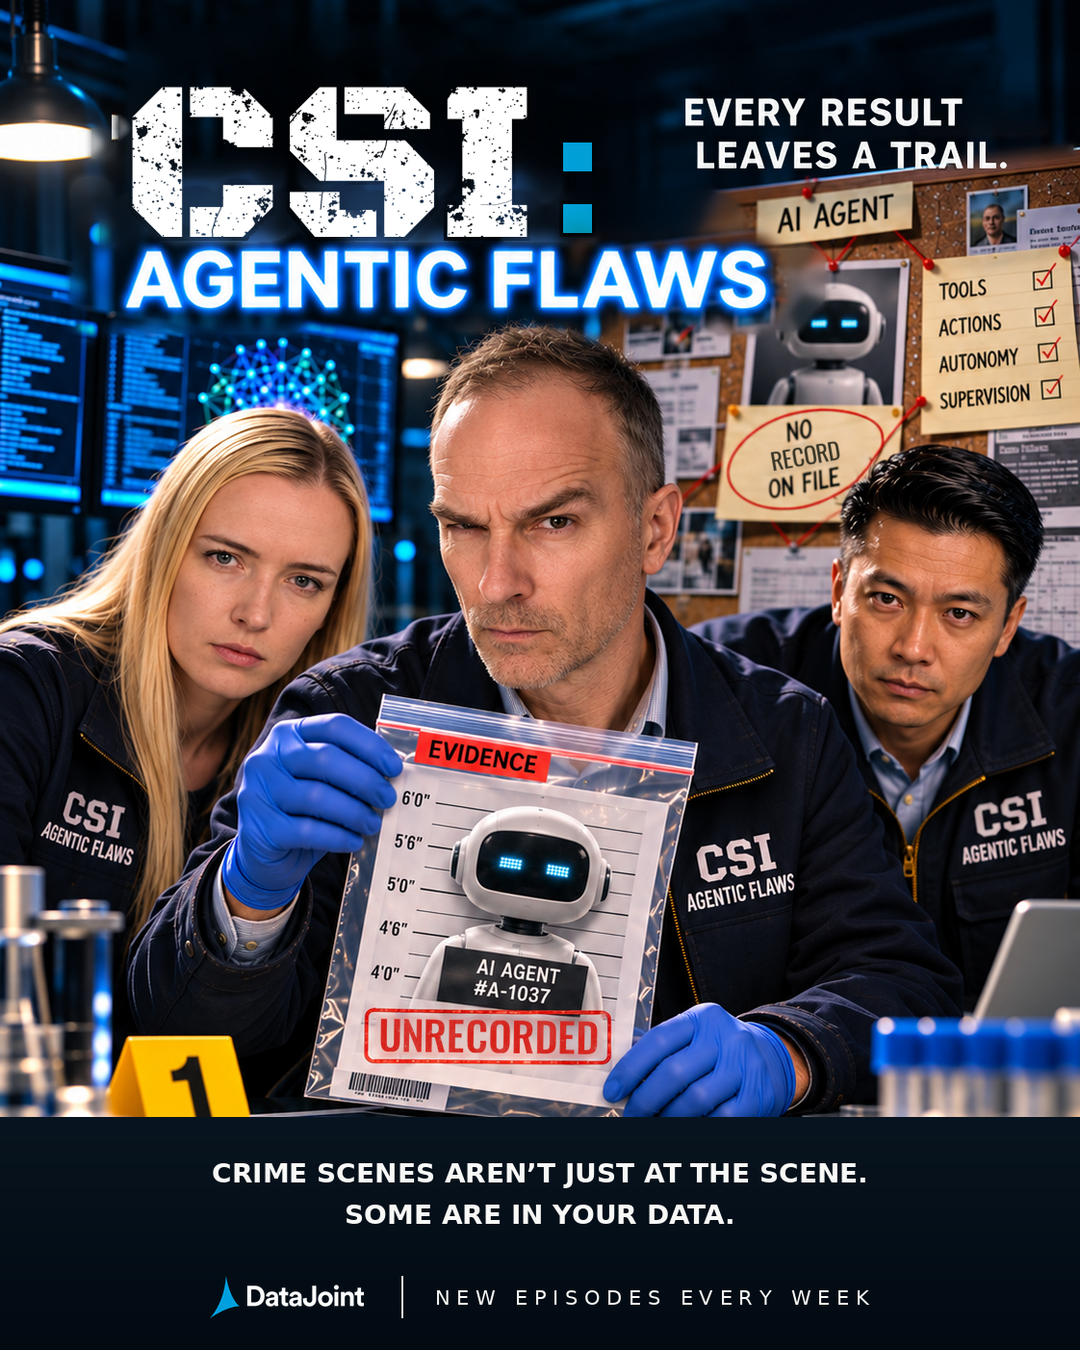
When a person produces a result, the person is the audit trail. You can ask how they got there, and they can walk you back through it. When an agent produces results at scale and nothing records how, you don’t have an audit trail — you have a pile of outputs to trust on faith. The ones that are right look exactly like the ones that are wrong.
That’s the real exposure. Not that an agent makes mistakes — people make mistakes too — but that an ungoverned agent makes them fast, confidently, and without a record anyone can check.
An agent does the wrong thing as fast as the right thing, and logs it the same way. Most agent setups keep an audit log, and in a regulated lab they have to. But an audit log records events, not derivations. It says who ran what, and when. It doesn’t say which inputs and which version of the code produced a given result, and it points to outputs it doesn’t hold: if a file is overwritten later, the log still points to it and nothing flags the change.
Part of it may be the agent’s own account of what it did, which can be wrong the same way the answer can. And a complete log of a wrong result still passes review. That’s the larger risk: the audit log makes an ungoverned agent look governed.
Harnesses are for horses
The industry’s answer so far is the harness: wrap the model in constraints and hope they hold. Right instinct, wrong layer. You can’t make an agent trustworthy by tightening a leash around the model. An agent is only as accountable as the workflow it runs on. Most agents already have a harness. What they lack is a record. A harness limits what an agent can do; it keeps no account of what the agent did.
Ground the workflow, and the picture changes. In a grounded workflow the design is the operation: the steps an agent takes are the same formal structure that defines the science, and every step writes its own record as it runs. The agent doesn’t have to be trusted to be honest about what it did, because what it did is written down — the inputs it used, the code it ran, the result it produced, bound together.
Now the agent can move fast and be checked. A person can walk any result back to its origin. Another agent can pick up where the last one stopped and reproduce it. The speed stays; the faith requirement goes.
The racetrack, not the leash
Harnesses are for horses. What a fast, powerful thing needs isn’t a tighter restraint — it’s a track built for speed that it cannot leave. Workflow grounding is the racetrack. The agent runs flat out, and the track keeps it honest.
That is the difference between an agent you deploy and an agent you can defend. One is a demo. The other is something a regulated lab can put its name on.
The readiness question
Before you put an agent on a workflow, ask one thing: if it did the work, could you prove how?
If the answer is “we’d trust it,” the agent doesn’t have a racetrack, it has a head start. Ground the workflow first, and the speed becomes an asset instead of a liability.