This is the written version of the talk I gave at Lab of the Future Europe in Amsterdam on 23 September 2026, in the AI to Innovate session. Sources, figure credits, and further reading are at the end.
Agents now do real scientific work, and the bottleneck has moved from what a model can do to what a team can check. Workflow grounding is DataJoint’s answer: agents read and extend the same declarations the work runs on, so every result traces to its inputs, its code, and the decisions behind it. A harness makes a model useful for one campaign. A formally defined workflow is what lets the work compound after the agents are gone.
The Lab of the Future Europe congress spent two days in Amsterdam on one question: what scientific work will look like when we make full use of automation and artificial intelligence to solve the hardest problems in medicine and life sciences. Automation, connected instruments, digital CMC, and AI running through all of it.
Instruments stream into shared stores instead of onto a workstation under the bench. Notebooks and inventory systems speak to each other. AI agents read a protocol, write the analysis for it, and call the tools to run it. In synthetic chemistry, propose–make–measure cycles close with nobody in the middle.
The possibilities feel intoxicating. Hand an agent a question and it proposes the work, runs what can be run against the data already in hand, and comes back with candidates ranked and its reasoning attached — for many questions at once.
At DataJoint we implement the scientific data foundation for research teams in pharmaceutical, clinical, and academic research. So the question we keep asking is whether the work compounds: does the group know more than it did, in a form the next question can use? That is a question about the workflow, not about the agents, and it gets harder to answer the longer the agents run before anybody asks it.
The bottleneck moved
Today, agents analyze the literature covering an entire domain. They propose and execute statistical analyses. They propose hypotheses, and they design experiments, protocols, and methods. It feels as though we should be able to solve problems that were out of reach, not only to work faster.
The progress has been rapid, and it has created new bottlenecks.
Ask a room of scientists what goes wrong when they work with capable agents, and the answer is almost never that the model was not clever enough. The most common complaint I hear is this: all I do is review what the AI produced, and I am behind.
Agents generate copious output that looks good. It reads as plausible, often as insightful and promising. And every so often there is an embarrassing, inexplicable mistake — the wrong data used, or two datasets silently mismatched.
That is the hard part. Errors you miss, inside work that looks right. How do we know which conclusions are trustworthy? And will we be able to defend them six months or a year from now?
Agents are wonderful brainstorming partners. Longer stretches of unattended work that lead to decisions need a much tighter level of rigor, and rigor is a property of the workflow rather than of the model.
How AI gets grounded
AI agents have improved in two ways: model capabilities and their grounding in the subject matter. Over three years the models gained larger context windows, better tuning, tool use, and reasoning they can explain.
The grounding is our ability to adapt a model to your subject matter, your questions, and your data. We have been through several rounds of this, each one tightening the grounding of an answer in the relevant data and making the answer easier to check against it.
| Era | How knowledge is reached and checked |
|---|---|
| 2021–23 · fine-tuning | absorbed into the weights — not checkable |
| 2022–24 · prompting | pasted into the window — by reading it |
| 2023–24 · retrieval | ranked passages — by following the citation |
| 2025 · context engineering | assembled before the answer — by the context engineer |
| 2025 · MCP | live query into your systems — by asking the system again |
| 2026 · science harnesses | assembled per campaign — by the code and reasoning it records |
| now · workflow grounding | curated as the work runs — traced to inputs, code, decisions |
The second column describes the checkability of the data used. A model weight cannot be asked where it came from. A citation points at a document but does not reproduce its derivation. A live query tells you what a system holds today, but not how it got there.
The newest of these is the science harness, a term now doing a lot of work in the field. A science harness is the environment built around a model that gives an agent tools, memory, compute, and a record of what it did. Kosmos, from Edison Scientific, and Claude Science, from Anthropic, are two of the best-known. They are serious engineering, and the record they keep is real evidence: it names what ran, on what, and when.
If we think of models as wild horses — strong, intelligent animals with minds of their own, entirely capable of acting destructively — then a harness is what lets them do useful work on the things you care about. But a harness is fitted to one horse for one race. What you also need is a track.
A track sets the lanes so that many horses can run at once, at full speed, with checkpoints along the way. And when you lay out a track, you make the straights long: long enough for an agent to do real work, to branch, to iterate on a design, and to come back with findings for a decision instead of questions along the way.
The earlier grounding methods wrapped around the model. They are model-centered approaches, and their aim is to maximize and showcase what a given model can do. A harness reaches your experimental data from the outside, and the one thing it cannot check is the thing you are judged on.
Workflow grounding
Workflow grounding starts from the other end: from the scientific workflow the lab actually performs. An agent is grounded in that workflow when it reads and extends the same declarations the work runs on — the entities, the dependencies between them, the code that produces each result, and the state of every derivation. The context is not assembled around the model; it is the workflow itself, and it outlasts the agent that used it. This is where much of the next few years of effort will go.
Other speakers at this congress described something close to it in their own words — multiagentic workspaces, and multi-agent orchestration as the layer that connects capabilities into coherent scientific workflows: the shared, persistent environment any number of agents plug into, defining the tools, the interfaces, the guardrails, and the rules for operation and record keeping. Different words, converging on the same conclusion: the durable object is the workflow, not the agent.
The self-driving-laboratory work arrives at it from synthetic chemistry rather than from data infrastructure: La Agente Óptima, from the Acceleration Consortium, separates the agent’s reasoning from the executed campaign and keeps a persistent optimization state between them, so that auditability follows from the architecture instead of from logging what the model said. (A survey of data agents published five days after this talk extends the term to a workflow harness, and lists among its open problems that what one run learns does not reach the next — which a harness cannot fix, because it dissolves with the run that used it.)
So how should we know whether any of this is working? Usually we measure how much faster we produce results with AI assistance. But the more important question is what is left at the end. After a year of such work, will you have a solid body of work that the next phase can build on? Or a year of copious documents that nobody — including you — can explain, defend, or reproduce?
It will not matter nearly as much how much work was produced, or how fast.
Precise notation lets knowledge compound
I have heard many people say that in 2026 the hottest programming language is plain English: whatever you can articulate clearly and precisely, your agent can deliver. There is something real in that, and there is a trap in it.
We may be living through a period much like how mathematics was done a thousand years ago. Arabic mathematicians in the Middle Ages could solve quadratic equations. But they did it, and taught it, in copious prose with diagrams. Here is a ninth-century solution to a quadratic equation, translated into English — about ninety words of correct reasoning that you can follow, and cannot transform.
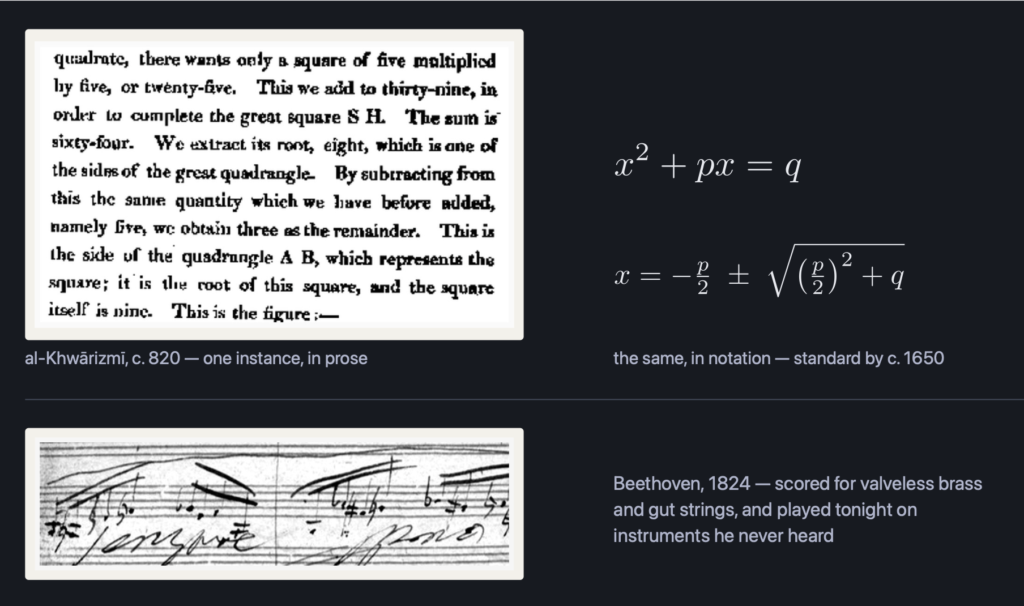
Precise notation lets knowledge transform, compound, and be checked.
The notation that evolved over the following eight hundred years is far more than shorthand. It expanded our cognitive capacity to transform expressions and derive new results. The same equation now takes two lines, and schoolchildren learn it in every culture on earth.
Notation also makes work independent of the machinery that carries it. Music could not be expressed in prose. Before musical notation, music passed by ear from master to pupil — which is how a great many research teams still operate. Beethoven scored the Ninth in 1824 for valveless horns and trumpets, gut strings, and keyed wooden flutes. Within a generation of his death, valved brass was taking over from the horns and trumpets he wrote for, and tonight the same score is played on instruments he never heard. It never needed rewriting, because it specifies the music and not the machinery.
Research workflows need that same independence. The instrument is replaced, the cluster is decommissioned, the file format is superseded, the vendor is acquired — every one of them on a shorter cycle than the science. A workflow that exists only as the scripts that happen to run it expires with them. A workflow written in a formal notation moves, because what it specifies is the work rather than the machine that ran it.
Precise notation lets knowledge transform and compound.
Software has run this experiment too. In the 1960s and 70s it was thought that programming would become more accessible if programs read like English sentences, and that push produced COBOL and the fourth-generation languages. Computer scientists have since found algebraic notation the more potent form, and the English-like programming languages have faded. The exception is SQL, a relic of that era that survived because the vendors standardized it (ANSI in 1986, ISO in 1987), so a query written for one database runs on another with minor changes. People outside programming still use it every day: a formal language, scoped to one domain, that a person can read.
Notice where agentic AI has made its most impressive progress: exactly the domains that already had precise formal notation and verifiable results. Mathematics and programming. That is where a model can be trained against a verifiable answer under clear rules.
The same holds for research workflows. To invent a workflow, to transform it, and to judge whether it is any good, we need a way to express it precisely and formally — so that humans and machines both understand it unequivocally.
A formal language for research workflows
So what language do we use to express a research workflow and reason about it?
We already have several domain-specific languages, for data, for computation, for infrastructure, and for governance. A real workflow needs several of them at once, and each is correct inside its own scope.
| Language | What it specifies, and what it leaves out |
|---|---|
| CWL, Nextflow, Snakemake | A directed acyclic graph of tasks with typed inputs and outputs — plainly, the steps and the order they run in. It leaves out the entities those steps produce: results are files the engine does not model, so nothing carries a result’s identity or its relation to the results on either side of it. |
| Terraform, Helm | A declarative target state for infrastructure, reconciled by a control loop — plainly, the machines and services, and what correct looks like. It leaves out the science: it can tell you a cluster is running, and nothing in it records what ran there. |
| Cedar, OPA | Authorization policy — principals, actions, resources, and conditions, evaluated per request; plainly, who may do what. It leaves out what the data is: a policy permits a read without saying what was read, or how that row came to exist. |
| dbt | SQL transformations with declared dependencies, materialized and tested inside a warehouse — plainly, how one table is built from other tables. It leaves out acquisition, instruments, computation that is not SQL, and work that is queued rather than done. |
| SQL DDL | Relations, domains, keys, and integrity constraints — plainly, the structure the database will hold. It leaves out how any of it came to be: derivation lives in code outside the schema, so a row cannot name what produced it. |
| Relational Workflow Model | Entities, their dependencies, the code on each, the constraints, and the state of every derivation, in one declaration carrying structure, dependency, and transformation together — plainly, the workflow itself, as a database that computes it. It leaves deployment and access control to the rows above, by design. |
The lacks differ in detail and agree in kind: none of these languages carries the work itself. They describe a static structure, and scientific work is not static. It branches. It is rerun with a changed parameter. It is partly computed and partly waiting. In science, how a result was derived is the contract, and a specification that leaves derivation to an engine outside itself has left out the part that matters.
A traditional database records what happened. A computational database defines how it happens.
For this purpose we developed the Relational Workflow Model: a semantic refinement of the classical relational database that makes computational transformations a native part of the schema. It is the language for constructing and evolving a scientific data foundation, and we develop it as an open standard, so that projects built on it stay freely interchangeable.
The DataJoint library is the Apache-2.0 reference implementation. The argument for it as a formal language, worked through against a relational ERD of the same pipeline, is in Schema as Workflow Grammar.
The scientific data foundation
A formal way to express and transform workflows is what lets us define a data foundation in a real lab.
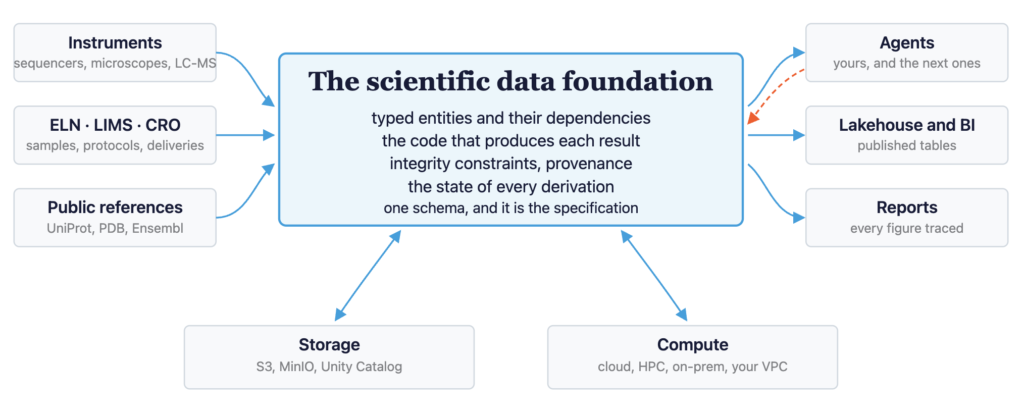
DataJoint provides the scientific data foundation where scientific work is codified as formally defined, self-executing workflows — free to evolve while their integrity, provenance, and reproducibility hold up by design — so that people and their AI agents can build on them with full trust.
It holds the typed entities and the dependencies between them, the code that reproduces each result, the integrity constraints, and the state of every derivation. It does that as a relational schema, and the schema is the specification of the workflow.
And it fits the infrastructure you already have: the instruments, the systems of record, the lakehouse, the compute. Instruments keep acquiring and systems of record keep their records; what arrives lands against a declared entity. The bytes stay in the object store you already run, because what the foundation holds is the entity, its lineage, and the code that produced it, not the payload.
The orange path on the right of that diagram is the only arrow a machine does not cross by itself. Agents read the schema and the job state, and their changes come back as declarations a person merges.
Using this model, people and agents alike can understand, express, extend, and transform the workflow as the project evolves.
The operational cycle
For the sake of this discussion, model scientific operations as a loop: you design the work, you operate it visibly, and you explain what you learned and how you know it.
Every group draws its own version of this loop, and nothing that follows depends on there being three acts.
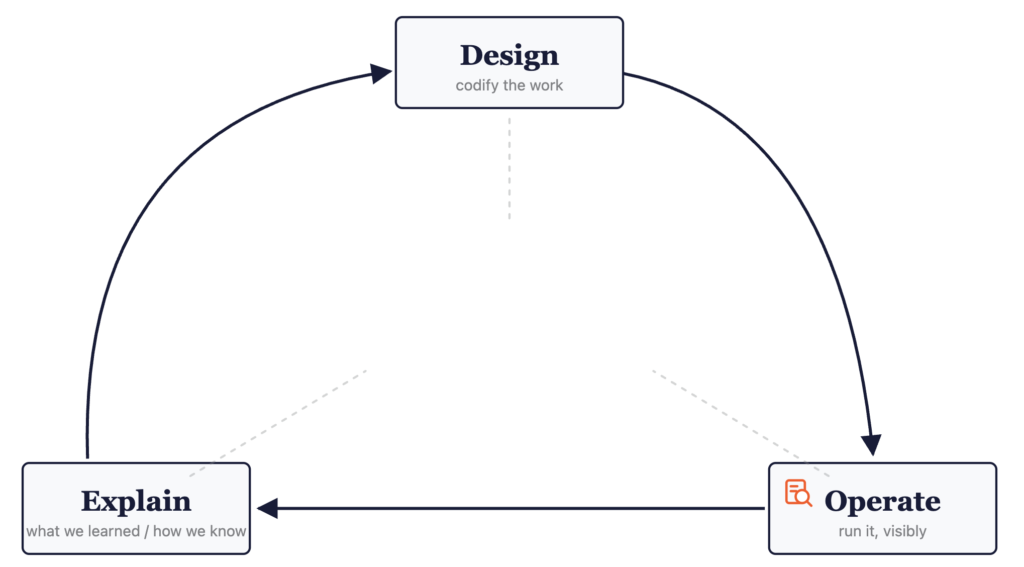
Regulation has focused on the Operate side of this loop — that inputs and transformations are traced and the data well governed. That is why Operate is the one act carrying an audit mark. The loop works. It produced the medicines in current use.
What is not typically modeled or formalized is the context in the middle: the motivations and aims, the decisions, the observations. That happens in meetings, in emails, in conversations — and it is where a team’s knowledge accumulates. Just as with music before notation, it passes from master to pupil, between generations of researchers. It aggregates, but not in a form an agent can use to build the next question on.
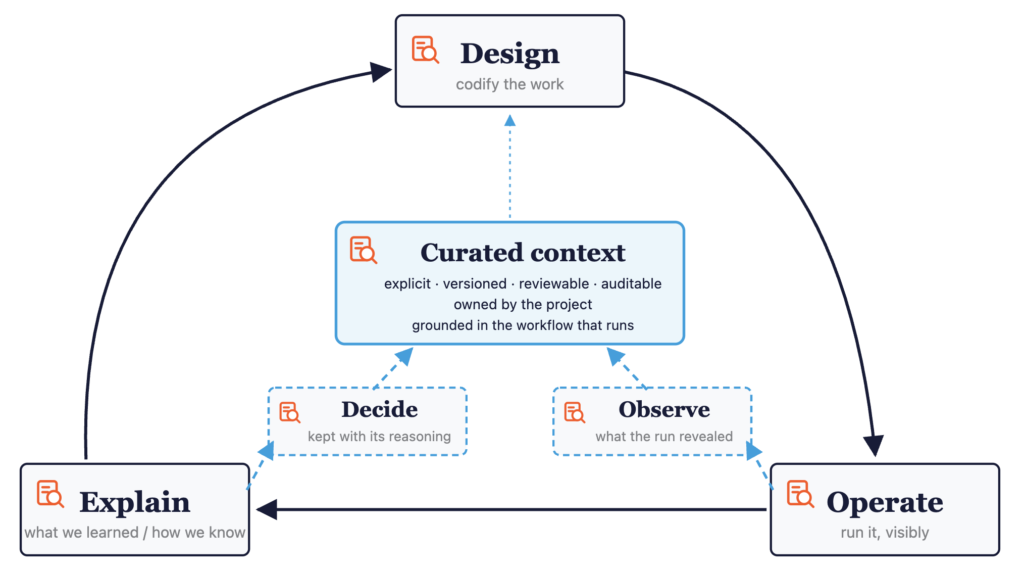
Implementing the scientific data foundation lets us formalize the Design and Explain parts of the loop as well, so that every act becomes inspectable, auditable, and analyzable by humans and agents alike — not Operate alone.
But it also requires a process for a shared, managed, curated context. That context becomes the grounding for the research team and for the agents, and it is aggregated while the work happens rather than collated afterwards. Learning is branched, reviewed, and merged together with the workflow it belongs to — the git-based process, applied to what a project knows. Which means bringing that context out of the emails and the Zoom calls.
Observe and Decide were always happening anyway. Somebody always noticed what a run revealed; somebody always decided to stop or to go on. What is new is that both are written down, so they tighten the cycle instead of dispersing from it.
Each turn of the loop leaves the project knowing more than it did before.
This is what we are building at DataJoint: agents that contribute at every part of the loop, helping the team operate the cycle and aggregate the context while the work runs, rather than reanalyzing after the fact.
An example workflow
Here is a workflow expressed in the Relational Workflow Model. This is the schema diagram, where each node is a table representing a step.
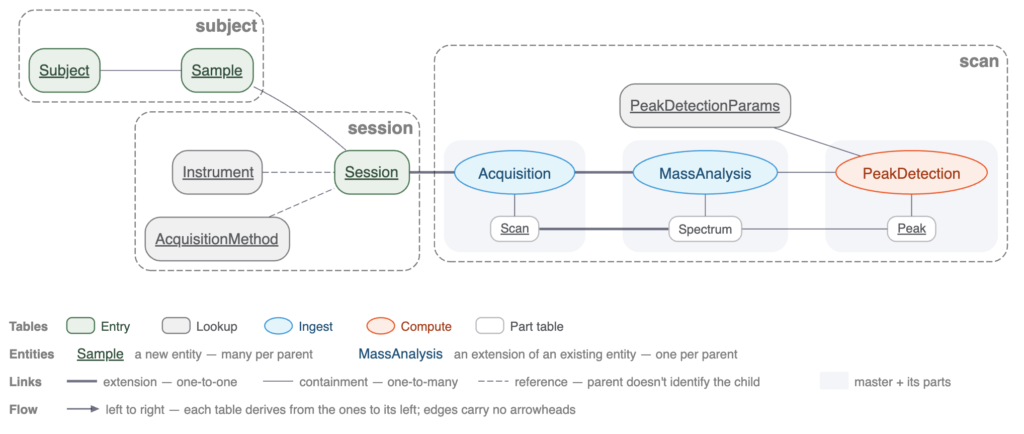
The connections between nodes are foreign keys, and they establish both data integrity and execution order. Rows in those tables are the workflow artifacts produced at each step. Whereas a traditional database captures entities and the relationships between them, a workflow database defines and executes how the data is collected and transformed.
This one is liquid chromatography and mass spectrometry — twelve entities, public, and the same workhorse in discovery, in bioanalysis, and in QC, so the shape of it travels. It is at once a relational database and an executable workflow: data entered by hand or from the electronic laboratory notebook, parameters in lookup tables, ingestion recorded, computations logged and versioned. Each node is a snippet of Python that declares the data structure, the dependencies, the order of operations, and the transformation the step performs — one construct doing three jobs, which is why they cannot fall out of agreement. Computation is part of the schema definition, not something bolted on beside it. And the figure was not drawn: it is generated from the pipeline it describes, so it cannot drift from it.
One story about this pipeline. It is the exemplary design in our own preprint — and when we asked an agent to review it against our own design checklist, it found defects. A table linked to its upstream by a comment saying the keys matched, rather than by a foreign key that would enforce it. This made us both proud and embarrassed — an agent we coached outperformed our own reasoning. It is fixed now, in the public repository. And we expect this to become a virtuous cycle: improvements inform new improvements, applied automatically.
With a formal representation of the workflow, agents become remarkably effective at designing, evaluating, and operating research workflows — and, as on this pipeline, they begin to catch what the original authors missed, on exactly the dimensions we care most about: quality and rigor.
A production pipeline at Johns Hopkins
DataJoint was first battle-tested in neuroscience mega-projects. The MICrONS project characterized the structure and function of a cubic millimeter of mouse visual cortex — some 75,000 neurons imaged in the awake animal, and an electron-microscopy reconstruction of more than 200,000 cells and half a billion synapses — and DataJoint was the backbone of the shared neurophysiology component from 2016 to publication. The results filled a Nature special issue in April 2025; our own account of the pipeline underneath them is A Better Data Engine for Brain Science.
The pipeline below is from the Shuler Lab at Johns Hopkins — subject and colony management, photometry, electrophysiology with GPU computation, running in production for years.
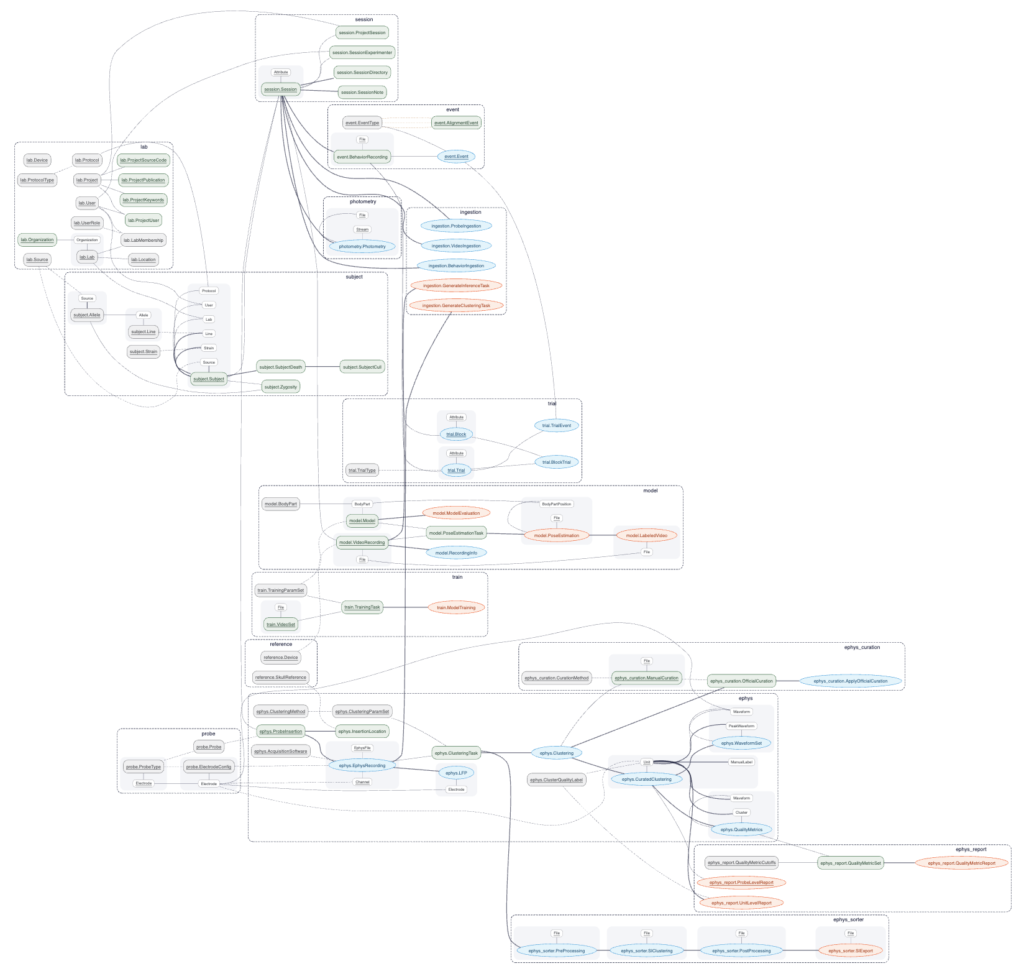
The first thing the picture buys is that the whole operation is one legible object. Manual entry, acquisition, heavy computation, and reporting sit in one graph, so a question about any result is answered from the structure rather than from whoever happened to run it.
The second thing is that the schema follows the lab’s own code. When the code in their repository changes, the structure extends with it, so code and schema move together instead of drifting apart. Marshall Hussain Shuler, quoted in our April 2025 Nature Research Custom feature: “We have already saved months and ran experiments that we never could before.” Two different units in one sentence — months saved is throughput, and experiments that were not previously possible is feasibility, which no hourly rate prices.
Zoom into the electrophysiology chain and you can see the grain of it: the recording as it came off the probe, a clustering task carrying its parameter set, the clustering itself, and curation as its own declared step. Methods and their parameters are entities in their own right, not arguments buried in a script. So the pipeline keeps evolving as the lab takes on variations of the experiment: change a setting, run it again, and you get a second result beside the first rather than one that quietly replaced it.
Later in the pipeline the work becomes analysis, reports, and figures — and figures are computed through the same dependencies as everything else. A figure is normally the least governed thing a laboratory produces: made in a notebook, exported, pasted into a deck, and from that moment disconnected from the analysis it summarized. Here, recomputing the analysis recomputes the figure with it. A figure in a deck is an orphan, and in a regulated laboratory an orphan is an audit finding.
Trustworthy AI is achieved by distrusting AI
So how do we defend what we learn, when much of the work is proposed and performed automatically? Workflow grounding lets us turn agents loose on many things at once, which makes that question sharper.
Trustworthy has a technical definition now: the ability to meet stakeholders’ expectations in a verifiable way. That is ISO’s wording, in ISO/IEC TS 5723:2022, and the EU AI Act uses the same term. Verifiable — not persuasive, not well-documented, not confident.
Regulators on both sides of the Atlantic have written the same requirement into law and guidance. In the EU, the AI Act — Regulation (EU) 2024/1689 — names trustworthy AI as its purpose in Article 1, and for high-risk systems it requires automatic logging across the system’s lifetime (Article 12), information sufficient for a deployer to interpret the output (Article 13), and human oversight by people who can understand what the system did (Article 14).
Those high-risk obligations were then deferred by the Digital Omnibus on AI, Regulation (EU) 2026/1744, in force since 27 July 2026 — to December 2027 for stand-alone Annex III systems, and to August 2028 for AI embedded in regulated products — while the Article 50 transparency duties took effect on schedule in August 2026. The date moved; the requirement did not.
In the US, the NIST AI Risk Management Framework sets out seven characteristics of trustworthy AI, among them accountable and transparent and explainable and interpretable. And the FDA’s 2025 draft guidance on AI supporting regulatory decisions for drug and biological products asks sponsors to establish a model’s credibility for a stated context of use, before the result is relied on.
Read them together and the same requirement appears in each: a record that lets someone else check the work. Not one of them asks whether the output was impressive.
And so trustworthy AI is achieved by distrusting AI — by making it show its work, and by making that work inspectable and verifiable. Verifiability, curation, and accountability follow.
Verifiability. A claim can be checked instead of believed, because the derivation behind it is recorded as structure and not as narrative.
Curation. The context is explicit, versioned, and owned by the project, rather than accumulated inside an agent’s memory. Agents come and go; the workflow and the curated context are what endure. If a new agent — or a human researcher — cannot reproduce the work from that context, the work is not finished. We do not forbid agents that remember. We refuse to depend on implicit memories.
Accountability. Agents can run long stretches autonomously, and people decide at checkpoints. Workflow grounding is what defines those stretches: an agent loops on a branch of the workflow, and at the end of the stretch its work is verified before it is merged. A checkpoint is not a rubber stamp — the accountable person has to understand what actually happened. And in each of these frameworks, it is the human scientists who are held accountable, because they have skin in the game. The AI co-scientist, well, has no skin.
None of that caps how much runs unattended. The gates sit on the consequential calls, and everything between them belongs to the agent. Explicit, inspectable aggregation is what makes agents faster, not what slows them down.
Ground for the next agents
Agents are fast and powerful, and we should assume they are ephemeral. Ground them in a workflow that is formally defined and written in one schema, and rigor holds while the agents run at speed.
This approach takes work. What it buys is work that aggregates and compounds — which is also what your regulators and your own quality people will ask you for.
AI agents will keep becoming more capable, and they cannot be the entire difference. The difference is what the operational cycle accumulates. The work in front of us is to ground the workflow, so that knowledge accumulates while the work runs.
The ideal agent is the one you never see. The ideal process lets the scientist see the science itself most clearly: what a decision implies, and what an experiment actually revealed.
What are your agents standing on, and where does their work go?
References and figure credits
- Lab of the Future Europe 2026, Beurs van Berlage, Amsterdam, 22–23 September 2026 — lab-of-the-future.com/europe. The talk this piece is adapted from was given in the AI to Innovate session on 23 September.
- How to Accelerate Research with AI Scientists and Multi-Agent Orchestration — Rob Brown, Sapio Sciences, Lab of the Future Europe, 22 September 2026. The published agenda describes multi-agent orchestration as the layer that connects these capabilities into coherent scientific workflows — a formulation close to the shared environment this essay calls workflow grounding.
- Yatsenko, D., et al. DataJoint 2.0: The Relational Workflow Model. Preprint — arXiv:2602.16585. The formal definition of the model, its query algebra, and the substrate elements built on it.
- Schema as Workflow Grammar, DataJoint, 12 August 2026 — datajoint.com/news/schema-as-workflow-grammar. The formal-language argument, worked against a relational ERD of the same pipeline.
- Agents are Brains. They Need Bodies., DataJoint, 8 June 2026 — datajoint.com/news/agents-are-brains-they-need-bodies.
- Intrinsic and Extrinsic Provenance, DataJoint, 26 August 2026 — datajoint.com/news/intrinsic-and-extrinsic-provenance. Where a provenance guarantee comes from, and why integrity precedes it.
- ISO/IEC TS 5723:2022, Trustworthiness — Vocabulary, July 2022 — iso.org/standard/81608.html. The source of the definition of trustworthy used above: the ability to meet stakeholders’ expectations in a verifiable way.
- Regulation (EU) 2024/1689, the AI Act, in force 1 August 2024 — eur-lex.europa.eu. Art. 1 (human-centric and trustworthy AI as the stated purpose), Art. 12 (record-keeping), Art. 13 (transparency and provision of information to deployers), Art. 14 (human oversight) for high-risk systems.
- Regulation (EU) 2026/1744, the Digital Omnibus on AI, published 24 July 2026 and in force 27 July 2026 — eur-lex.europa.eu. Defers the high-risk obligations to 2 December 2027 for stand-alone Annex III systems and to 2 August 2028 for AI embedded in regulated products; the Art. 50 transparency duties applied from 2 August 2026, with a four-month grace period on the Art. 50(2) marking obligation for systems already on the market, ending 2 December 2026.
- NIST AI 100-1, Artificial Intelligence Risk Management Framework (AI RMF 1.0), 26 January 2023 — nist.gov/itl/ai-risk-management-framework, doi:10.6028/NIST.AI.100-1. The seven characteristics of trustworthy AI, including accountable and transparent and explainable and interpretable.
- FDA, Considerations for the Use of Artificial Intelligence to Support Regulatory Decision-Making for Drug and Biological Products, draft guidance, January 2025 — fda.gov. A risk-based credibility assessment framework for an AI model in a stated context of use.
- MICrONS Consortium, Functional connectomics spanning multiple areas of mouse visual cortex, Nature 640, 435–447, 9 April 2025 — doi:10.1038/s41586-025-08790-w. The flagship paper of the April 2025 Nature special issue, The MICrONS Project. DataJoint was the data backbone of the neurophysiology component, selected in 2016.
- A Better Data Engine for Brain Science, DataJoint, 22 April 2025 — datajoint.com/news/better-data-engine-for-brain-science. Our own account of the MICrONS pipeline and the labs that followed it — republished, slightly expanded, from the Nature Research Custom two-pager of April 2025, which is the source of the Marshall Hussain Shuler quotation in A production pipeline at Johns Hopkins (the two-pager as printed).
- Müller, M., Bai, J., Gottstein, W., et al. La Agente Óptima: Towards Agentic Self-Driving Laboratories, 3 September 2026 — arXiv:2609.04564. LLM reasoning separated from the executed campaign, with a persistent optimization state between them, so that control returns to the agent only when progress needs interpretation. Evaluated on two physical platforms, including a five-day flow-chemistry campaign that raised yield from 30% to 59% over 23 experiments. Presented at this congress by Willi Gottstein of the Acceleration Consortium, in the Orchestrated Lab track on 22 September.
- Kosmos: An AI Scientist for Autonomous Discovery, Edison Scientific, November 2025 — announcement, arXiv:2511.02824. A structured world model as the agents’ shared memory, assembled per run and dissolved with it: up to twelve hours, some 200 rollouts and 1,500 papers, every conclusion cited to code or to literature.
- Zhou, H., Zhang, Y., Du, J., et al. Towards Reliable AI Data Scientists: Data Agents with Workflow Harnesses, 28 September 2026 — arXiv:2609.35255. Published five days after the talk, and cited here in the note above rather than in its argument. A survey organizing LLM data agents around five stages — perception, planning, execution, verification, repair — under what it calls the workflow harness, “the control structure that governs how this trajectory is constructed, monitored, and revised.” Its diagnosis matches the one above: “silent failures can persist even when individual components function correctly.” Two of its four open reliability problems — missing experience transfer, and the missing verification-repair repository — are the case for a durable object outside the run.
- Claude Science, an AI workbench for scientists, Anthropic, 30 June 2026 — anthropic.com. Curated connectors to public reference databases, jobs submitted to the lab’s own HPC cluster over SSH, and an auditable history — exact code, environment, and message history — on every output.
lcms-demo— the twelve-entity LC-MS pipeline, public at github.com/datajoint/lcms-demo.
Figures: the operational-cycle pair, the foundation in context, and the notation composite are adapted from the Lab of the Future deck; the LC-MS schema and the Shuler Lab pipeline are dj.Diagram output generated from the schema definitions in each pipeline’s public code repository; neither diagram draws on any data. The al-Khwārizmī plate is from Rosen’s 1831 translation of the Algebra and the Beethoven plate from the autograph of the Ninth; both are public domain.