DataJoint is a validated Built-on partner in the Databricks Brickbuilder Partner Network (Bronze tier)

  • Can you trust it?

    Can you trust it?

    Reproducibility asks whether you can rebuild a result. Trust asks something you face far more often: can you rely on a result you did not produce yourself? A teammate’s, an agent’s, last quarter’s from someone who has since moved on. The weak answer is that you trust whoever made it. The strong answer is that you do not have to, because the record lets you check it.

    The result you didn’t make

    Reproducibility is about your own work. Trust is about everyone else’s. In production, most of the results that cross your desk are not yours. You did not run them. So the question that governs your day is no longer whether you can rebuild your own work. It is whether you can rely on work you did not do.

    Trusting the person, or trusting the record

    There are two ways to trust a result. You trust whoever produced it, or you can check it yourself. The first feels efficient, and it is a liability: it cannot be checked, and it walks out the door when that person does. The second is the only kind of trust that survives turnover and scale.

    Trust that depends on who made the result does not scale. Trust that lives in the record does.
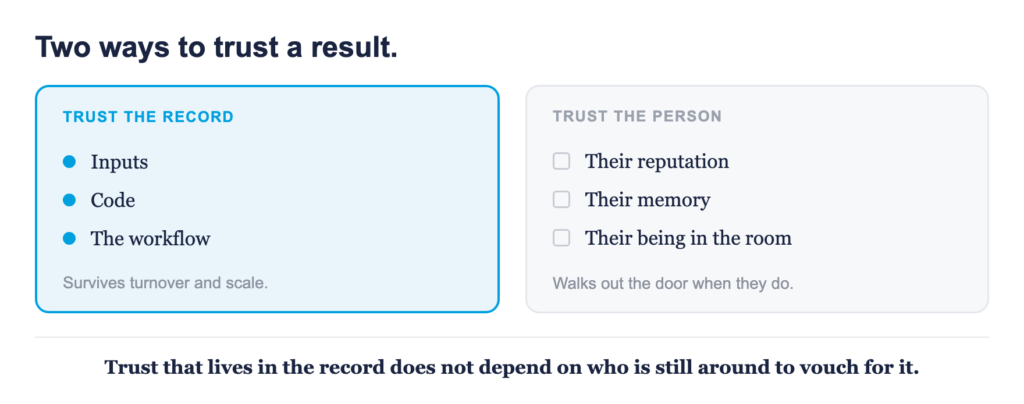
    Figure · Two ways to trust a result

    Agents make this urgent

    A proof of concept has a human in the loop who vouches for the output. You trust the result because you trust the person standing next to it. Production does not work that way. Agents produce results faster than anyone can personally verify, and the person accountable for a result did not watch it being made. You cannot trust that volume by trusting an author. You can only trust what each result carries with it.

    A result that carries its own evidence

    You can lean on review and reputation: they are good, so I trust them. It helps, and it decays, because it rests on the person you are trying not to depend on. The stronger arrangement is a result that arrives with its inputs, its code, and the workflow that produced it, so anyone, or any agent, can check it without asking whoever made it.

    That works only when the record is not something the author kept by hand. The result cannot exist without its inputs and the code that computed it, so the record cannot drift from the result. Trust stops being a relationship. It becomes a property of the result.
    The last result you acted on that you did not produce yourself: did you trust it because you could check it, or because of who handed it to you?

  • Which result do you trust?

    Which result do you trust?

    Biomedical researchers struggle to reproduce their own work. In a 2024 survey of 1,630 of them, published in PLOS Biology, 72% said their field faces a reproducibility crisis. Of those who had tried to repeat one of their own studies, 43% could not.

    That last number is the stranger one. Reproducing someone else’s work means a different lab, different hands and different reagents. Reproducing your own work removes most of those differences, and it still fails. You run the same analysis a second time, get a different number, and no one can say why. The first run is already in the paper. Now you have two results and no way to tell which one is right.

    This kind of failure is quieter than fraud and does more damage, because nothing flags it. A result you cannot account for looks the same as one you can, until someone asks you to account for it.

    Why results diverge

    A result can change between runs for reasons that never show up in the analysis: a parameter set by hand and never written down, a library that updated, a random seed, a different machine. A reviewer would not catch any of these, because the analysis looks the same both times.

    So running it again does not settle anything. A third run may give a third number. Without a record of what each run used, you are comparing results you cannot explain.

    The fix is a record of every run

    It would be easy to claim that the same inputs always give the same answer. That would not be true. Much of what changes a result sits outside the code: software versions, seeds, hardware. No workflow can keep all of that fixed.

    What a workflow can do is keep the record. In a grounded workflow, every run stores exactly what produced it: the inputs, the code version and the parameters. When two results differ, you put the two runs side by side and see what changed, such as a dependency or a parameter. You can also see which run matches the paper.

    This is the lineage claim from the first episode, applied to a second run, and it holds without conditions. The number may still move. The record tells you why it moved and which version to trust.

    Which one do you report?

    The runs do not all have to agree, but when they disagree you need to be able to explain why. Then when a reviewer, an auditor or your future self asks which result is correct, the answer is in the record and not in someone’s memory.

    A result you can account for is a result you can defend. A result you cannot account for is a liability wearing a lab coat.

    With the record, you do not have to guess which result to trust.


    Sources

    Cobey, K. D., et al. (2024). Biomedical researchers’ perspectives on the reproducibility of research. PLOS Biology, 22(11), e3002870.

    Trisovic, A., Lau, M. K., Pasquier, T., & Crosas, M. (2022). A large-scale study on research code quality and execution. Scientific Data, 9, 60.

  • Can you rerun it?

    Can you rerun it?

     Reproducibility is the real test of whether scientific data is ready. Not whether a result was written down, but whether it can be rebuilt on demand; by someone else, after the people and the systems have moved on. Most teams can show a result. Fewer can run it again. That gap is where AI validation and regulatory review tend to break.

    The request that separates companies

    In an evaluation I eventually ask for the same thing. Show me last year’s best result. Then rerun it, start to finish, while I watch.

    Most teams can produce the result. The figure, the readout, the number that went into a decision. Fewer can rebuild it. Not because anyone was careless, but because the result was never designed to be produced a second time.

    A reproducible result is a different object

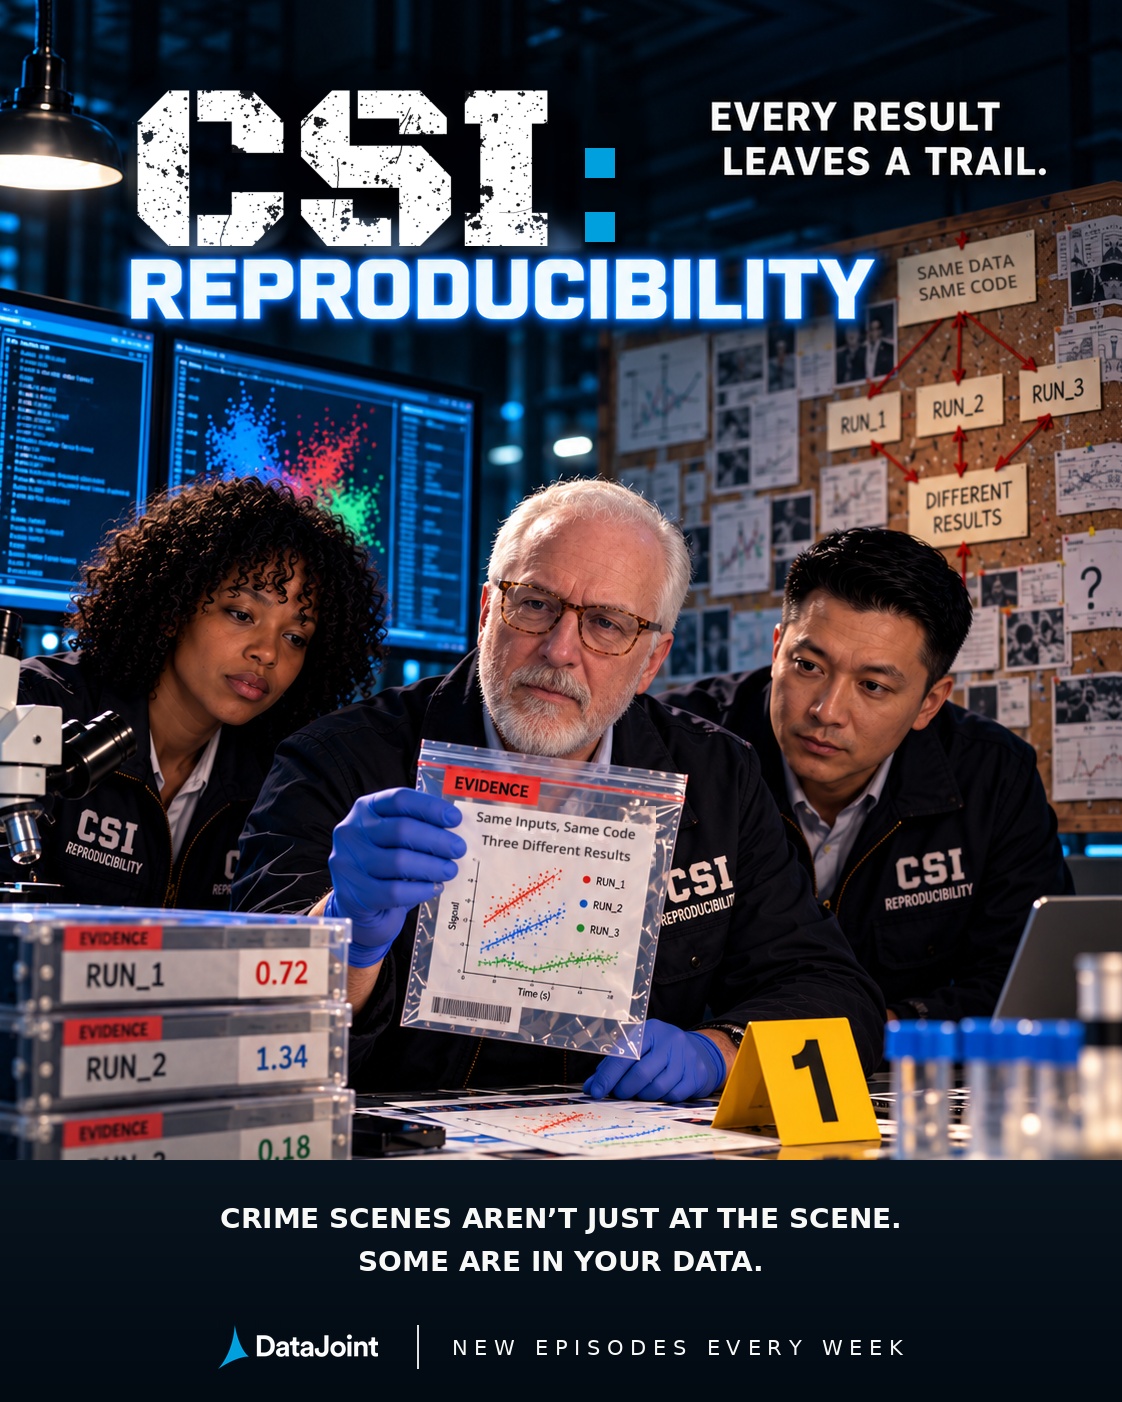
    A result you cannot reproduce is not a weaker version of one you can. It is a different kind of object. It records that something happened once. It cannot promise it would happen again

    The question is not whether it happened. It is whether it can happen again.

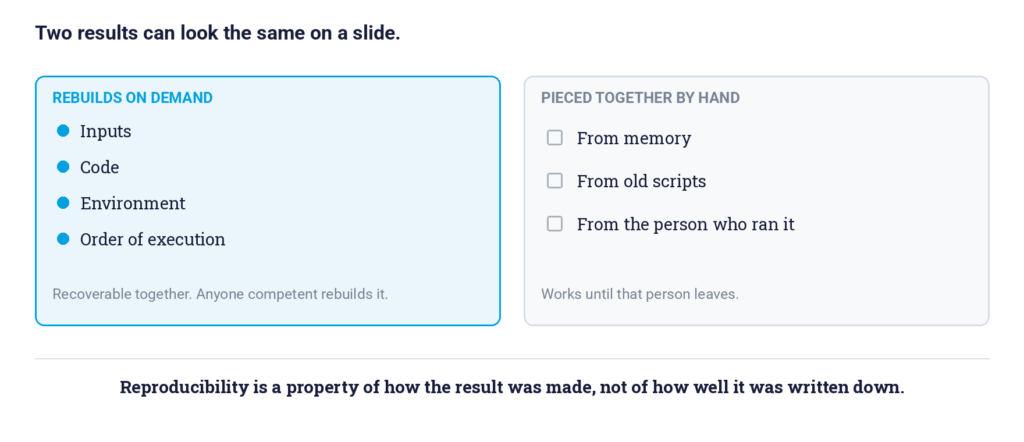
    That is not a quality gap you close with a better report. The report describes the result. Reproducibility is a property of how the result was made.

    Not a niche worry

    In 2026 the Brazilian Reproducibility Initiative, more than 50 labs working together, took a set of published biomedical experiments and ran them again. Depending on the criteria, 20% to 44% reproduced. Fewer than half. 

    This was not a survey or an estimate. It was the experiments, run a second time, by independent labs with nothing to sell. And a 2024 survey in PLOS Biology found that 72% of biomedical researchers already agree there is a reproducibility crisis. The people doing the work are not surprised.

    The part I sit with is not the number. It is why so much of it did not rebuild. The initiative traced much of the gap to methods that were written down but never written to be run again: steps left ambiguous, details that lived in one person’s hands. 

    Records were kept, protocols were written, reports were filed. The work still did not rebuild. Documentation was never the missing piece.

    Why ready and rerunnable are the same question

    A result reruns only when four things are recoverable together: the inputs, the code, the environment they ran in, and the order they ran in. Lose any one and you can still describe what happened. You cannot reproduce it.

    Most systems capture the first and narrate the rest. That is enough to pass an audit of the record. It is not enough to rebuild the result, which is a different and harder guarantee.

    What a vendor will not tell you

    Here is the concession. Most existing results will never be made rerunnable, and chasing them usually is not worth it. You do not go back and rebuild five years of work. You draw a line. You make everything after it reproducible by default, and you are clear about which side of the line a given result sits on

    The stronger version does not rely on discipline

    Knowing the line is the minimum. The better arrangement is a system that will not record a result it cannot rebuild, so reproducibility stops being a practice a person maintains and becomes a property of the record itself. That difference holds up when the person who maintained the practice leaves.

    The last time you were asked to reproduce a result, could you, or did you have to piece it back together?

    Surfacing that in a room costs an afternoon. Discovering it inside an AI validation costs the result, and every decision that leaned on it.


    Sources

    The Brazilian Reproducibility Initiative, “Estimating the replicability of Brazilian biomedical science,” eLife, reviewed preprint (2026)

    Cobey et al., “Biomedical researchers’ perspectives on the reproducibility of research,” PLOS Biology 22(11):e3002870 (2024)

  • Every result leaves a trail

    Every result leaves a trail


    Most labs rely on results that nobody can fully explain. The number is in a paper, a slide deck, or a decision that has already been made. Ask which inputs, which version of the code, and which run produced it, and often no one can say. This first episode is about that problem:

    a result that is still in use after the record of how it was made has been lost.

    A number is not a result

    A result is a number plus its provenance: the inputs it came from, the code that computed it, the parameters used, and the run that produced it. Without those, you have a value and no way to check it. A lot of lab data is in this state, in spreadsheet cells and in folders named final_final_v2.

    This works until someone asks how the number was produced. That might be an auditor, a regulator, a reviewer, or an AI system that reads your data and acts on it, which is more and more common.

    If the record was never kept, there is nothing to show them. Usually nobody made a mistake. The tools they used simply didn’t record how each result was made.

    The record has to come from the work itself

    The usual fix is discipline: label everything, keep the notebook current, name files consistently. That holds until a busy week, a quick re-run, or a handoff to someone new. Provenance that depends on people remembering is missing at the moment it’s needed.

    In a grounded workflow, each step records how its result was made at the moment it runs: what it used, what code ran, and what it produced. There is no separate documentation task. The design of the workflow is the operation, and every step writes its own record.

    Ask how a result was made, and look it up

    Once the record is automatic, the question that used to stall a meeting becomes a lookup. You can trace a result back through the analysis to the raw data, the instrument, and its origin. You can ask which results depend on an input that just changed.

    A new scientist, an auditor, or an AI agent can follow any number back to the moment it was made, without needing the one person who happened to remember.

    That is the difference between a result you report and one you can defend. The first asks for trust. The second shows the record.

    Every result leaves a trail. The work is to build the workflow that keeps it.

  • Where does your provenance stop?

    Where does your provenance stop?

    Automatic provenance covers what a system performs itself. At the boundary with instruments, vendor files and manual steps, the system cannot describe what happened because it did not do it. From that point on, provenance depends on a person keeping a commitment, and the strongest organizations know exactly where that line is.

    The more useful question is where it stops

    Provenance conversations are usually about coverage. How much do you have, how far back does it go. A more revealing question is where it ends.

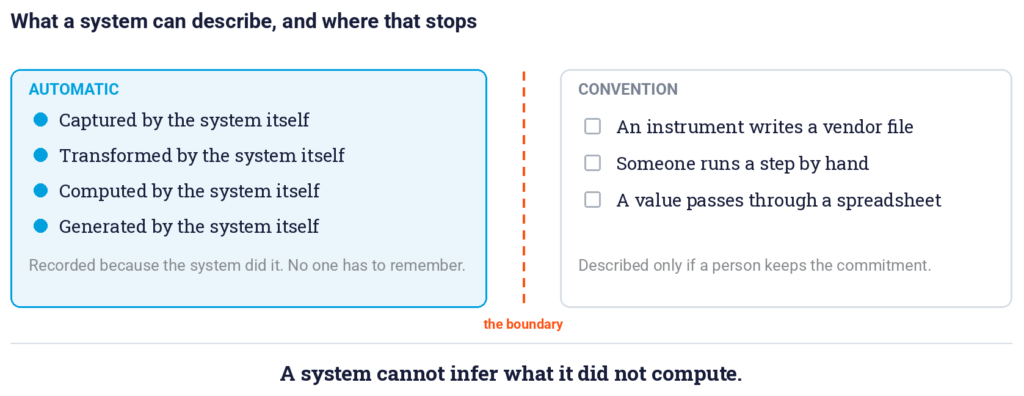
    A system can record every transformation it performed, because it performed them. No one has to remember, and nothing depends on discipline. That part is strong.

    What a system can describe, and where that stops.

    Then the work reaches a boundary. An instrument writes a vendor file. Someone runs a step by hand. A value passes through a spreadsheet on its way somewhere else. At that boundary the system stops being able to describe what happened, because it did not do it. A system cannot infer what it did not compute.

    What sits on the other side

    When I ask teams what happens between the instrument and the point where the platform picks the data up, the answer tends to be a version of the same thing: that part is a convention. Everyone knows to name the files correctly.

    ‘Everyone knows’ is not a record. It is a practice.

    A practice works for exactly as long as the people who hold it are the people doing the work. That is a shorter horizon than most coverage claims imply, and it is rarely written down anywhere that would survive a reorganization.

    Boundaries are not the problem

    Every real research environment has them, and any vendor claiming otherwise is describing a diagram rather than a laboratory. The argument is not for eliminating boundaries. It is for knowing precisely where yours fall.

    The organizations in the strongest position are not the ones claiming end-to-end coverage. They are the ones who can point at the boundary and name who is accountable on the other side of it.

    The strongest version goes one step further

    Knowing where the boundary falls is the minimum. The better arrangement is a system that refuses to accept data across that boundary without a source record attached, so a write that arrives with nothing is not a tolerated gap but a failed load.

    That turns the boundary from a place where discipline is required into a place where discipline is enforced, a materially different guarantee when the person who held the discipline leaves.

    Where does your provenance stop being automatic and start being a convention?

    If nobody can point to the line, the line is still there. It is just being crossed without anyone accounting for it.

  • Six questions to take into your next AI review

    Six questions to take into your next AI review

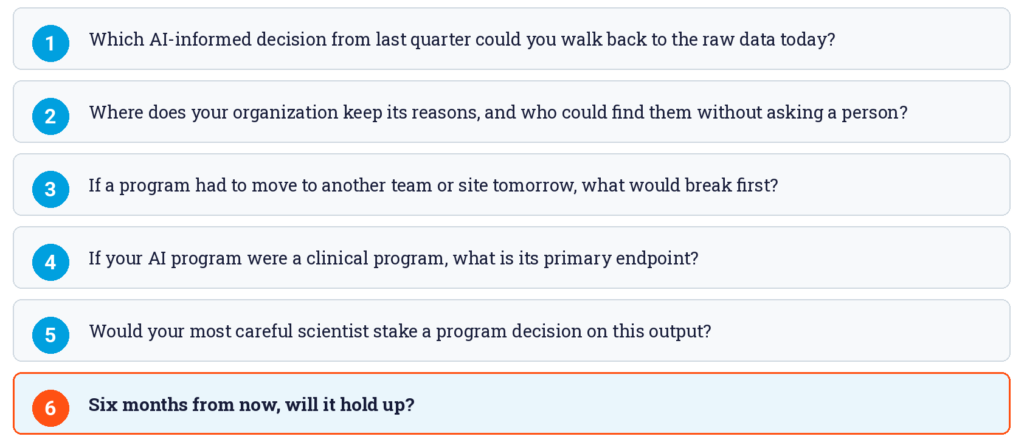
    Six questions, drawn from six weeks of conversations with pharma R&D leaders, that test whether an AI program will hold up under examination. None of them are technology questions. They can be answered in a room with no laptops open, and the answers say more about readiness than most maturity models.

    Six weeks of listening, six questions

    I started this series expecting to write about models and ended up writing about questions. Six of them kept returning in conversations with pharma R&D leaders, investors and technology partners, and they are collected here in one place.

    The six questions. Available as a single page.

    Why questions rather than answers

    Every AI maturity model I have been shown produces a score. Scores are useful for reporting and almost useless for deciding what to do on Monday. A question that cannot be answered points directly at the work.

    None of these are technology questions. They can be answered in a room with no laptops open, by people who know how the work runs.  The answers say more about AI readiness than any assessment I have seen.

    Infrastructure is not the exciting part of AI. It may prove to be the part that decides who gets to keep going.

    How to use them

    Take one into a review that is already scheduled. Do not announce it as an exercise. Ask it in the ordinary course of the meeting and pay attention to how long the room takes to answer.

    The pause is the finding. A question that produces four different answers from four people is telling you something a maturity score would have averaged away.

    The one that matters most

    The sixth question is the whole series. Six months from now, will it hold up? The first five are how you find out, and each takes a different route to the same place: whether the reasoning behind a decision will survive the people who made it.

    One note from outside the list. These questions are not hypothetical. The foundation that institutions built for the world’s most complex multimodal research is now running inside a top-five pharmaceutical company; where the same upstream questions carry higher stakes.

    What those teams share is not budget. It is that they treated readiness as the work, not a cleanup after the AI arrived.

    Which of the six can your organization not yet answer?

    That is the conversation I would like to have next, and it is a better use of a meeting than another readiness assessment.

  • Why scientists reject AI outputs they cannot reproduce

    Why scientists reject AI outputs they cannot reproduce

    AI adoption across biotech and pharma drops sharply in the areas closest to discovery decisions. The reason is not resistance to change. A scientist who acts on an output they cannot trace or rerun is absorbing risk the organization has not priced; so refusing is the correct professional judgment.

    A line worth pushing on

    The line I keep hearing this year, in some version, from every corner of the industry:  we no longer have a data problem. We have a confidence problem.

    Half the industry now says a version of that, which usually means the phrase has stopped doing work. So the better question is where the confidence problem lives, because it is not evenly distributed.

    It lives at the bench

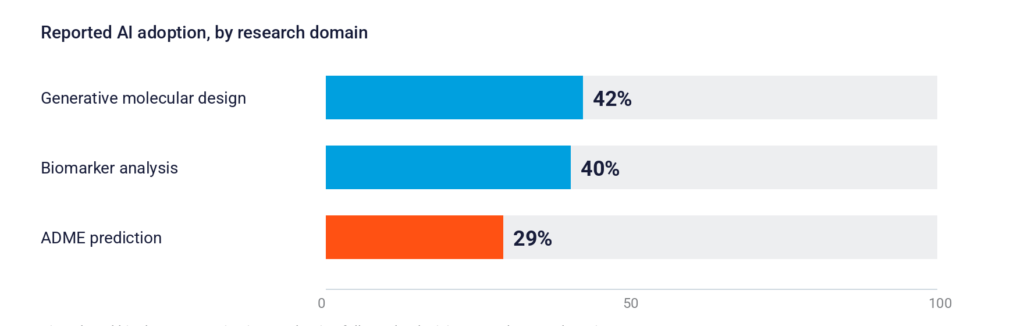
    Across biotech and biopharma organizations, reported AI adoption reaches 42% for generative molecular design, 40% for biomarker analysis and 29% for ADME prediction, as reported by Drug Discovery News in February 2026.

    Benchling 2026 Biotech AI Report, a November 2025 survey of ~104 biotech and biopharma organizations. Reported by Drug Discovery News.

    Those are the places where discovery decisions get made. Adoption falls as the stakes of the decision rise, which is the opposite of what a technology adoption curve normally looks like.

    Refusing is the correct professional judgment

    The standard reading of that data is scientist resistance, and it leads to more training and more change management. I think the standard reading is wrong.

    Declining to act on an output you cannot reproduce is not caution.
    It is the job.

    A scientist who acts on a confident answer they cannot reproduce is not being efficient. They are absorbing risk the organization has not priced and will not acknowledge until something goes wrong. Declining is not conservatism. It is the job.

    Confidence is a property of the system, not a state of mind

    Which means it cannot be trained into people. It comes from the same inputs and the same code returning the same result, every time, with a record of how it got there. When that is true, adoption follows without a campaign. When it is not, no amount of enthusiasm from leadership will move the number.

    This is also why the confidence problem and the data problem are not separate. Confidence is what a well-built foundation feels like from the outside.

    Would your most careful scientist stake a program decision on this output? If not, what would have to be true?

    The second sentence is the useful one. Whatever she names is your roadmap, and it will be shorter and more specific than any maturity assessment you could buy.


    Sources

    Benchling, 2026 Biotech AI Report, November 2025 survey
    Survey of ~104 biotech and biopharma organizations, US and Europe. 

    Drug Discovery News, The 2026 AI Power Shift, February 2026
    DDN’s coverage of the same report

  • Was your data made ready, or did it come out that way?

    Was your data made ready, or did it come out that way?

    Scientific data becomes AI-ready in one of two ways: as a consequence of how the work runs, or by being described after the work is finished. On paper the two look identical. The guarantees are not, because a retrofit depends on someone correctly describing afterward what happened, and it is never finished while new work keeps arriving.

    Two routes to the same document

    Scientific data becomes AI-ready in one of two ways, and the resulting documents can look nearly identical. What they guarantee could not be more different.

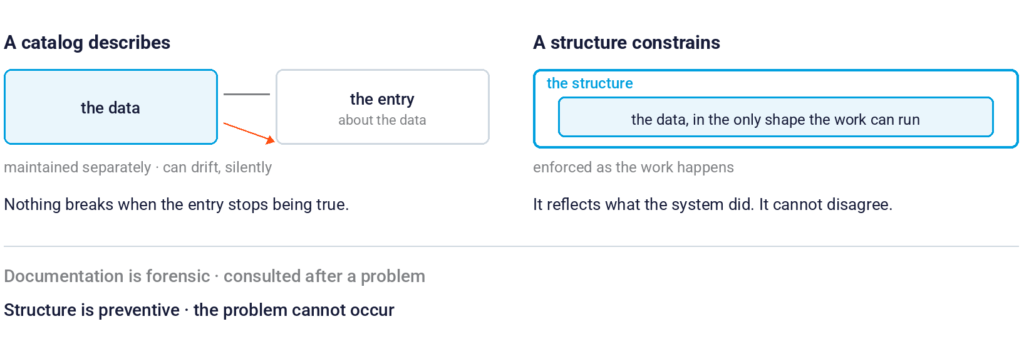
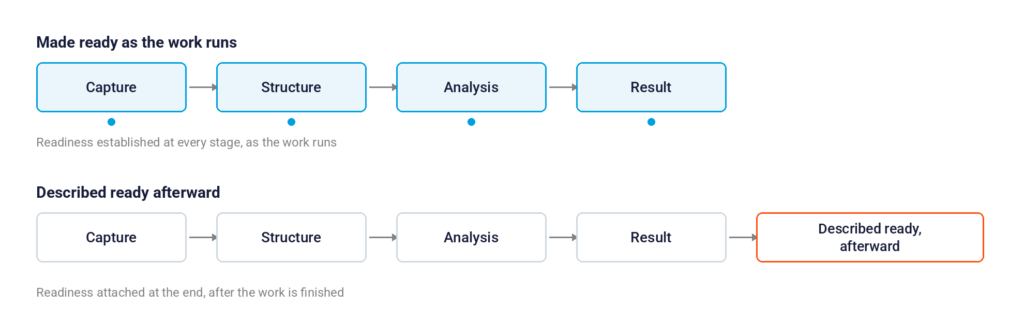
    The first route makes readiness a consequence of how the work runs. Structure is enforced as the work happens, and provenance falls out of execution instead of being a separate task somebody owns.

    The second attaches readiness to work that has already finished. Someone goes back, describes what happened, and records it.

    The same four stages. Two different points at which readiness is established.

    Why a retrofit does not stay finished

    When I ask teams deep into a retrofit what happens to work that ran before the project started, the answer is prioritization. When I ask what happens to the work running now, the pause is longer.

    That is the whole problem in one exchange. A race against production, and production does not pause.

    It is not an argument that retrofit fails. Retrofit works. What it cannot do is stay finished, because the process that created the backlog is still running.

    Retrofit is often the only honest option

    Nobody rebuilds twenty years of research because a strategy deck asked them to. For historical work, describing what happened is frequently the only route available, and doing it carefully is real work worth funding.

    The distinction that matters is between choosing retrofit for the past and choosing it for the future. The second choice usually gets made without anyone noticing it was a choice.

    Retrofit works. What it cannot do is stay finished.

    What the two approaches guarantee

    Work that produces itself in a ready state carries a record of what the system did. Work made ready afterward carries a record of what somebody believed the system did. Both are useful. Only one of them cannot disagree with the work it describes.

    Data that was made ready afterward carries one more assumption: that whoever did the describing understood what happened. Sometimes they did. The work that produces itself in a ready state does not need the assumption.

    For the work your team ran last quarter, did readiness happen as part of the work or after it?

    If the answer is different for last quarter than it will be for next quarter, that is progress. If it is the same, the retrofit is not a transition. It is the operating model.

  • If your AI program were a clinical program, what is its primary endpoint?

    If your AI program were a clinical program, what is its primary endpoint?

    The old question is retired

    Two years ago, nearly every leadership conversation I was in started the same way: do you have an AI strategy? That question has been answered everywhere, usually more than once. The one that replaced it is harder. What does AI change, and by when?

    Does it shorten the path to a candidate? Does it improve the quality of a go or no-go decision? Does it reduce the rework nobody budgets for? Or is it a feature?

    The number behind the shift

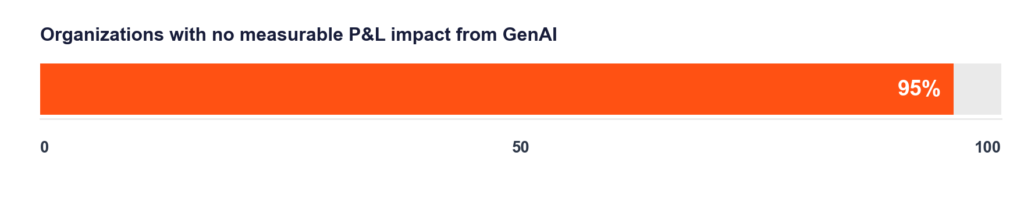
    MIT NANDA found that 95% of organizations saw no measurable P&L impact from an estimated $30 to $40 billion in enterprise GenAI spend.

    MIT NANDA, “The GenAI Divide: State of AI in Business 2025,” July 2025. 

    Pharma is not exempt, and the R&D leaders I talk with know it. The internal conversation has moved from ambition to accounting. I read that as healthy, not pessimistic.

    The budget asymmetry nobody names

    Here is the uncomfortable part. Most AI budgets fund what the model gives you. Almost nothing funds what makes the answer worth trusting.

    Most AI budgets fund what the model gives you. Almost nothing funds what makes the answer worth trusting.

    That asymmetry is why a well-funded program can produce a technically correct output nobody will act on. The money went to the half of the problem that demos well.

    The metrics that prove an AI program are not AI metrics

    They are R&D metrics. Cycle time from data to decision. The share of results that can be rerun without the original author. Time to answer an audit question. AI either moves those numbers or it does not, and all three can be measured this quarter without a new dashboard.

    The question I now hear from finance, in one form or another: if this were a drug program, what would the readout be? Most AI proposals do not have an answer. The ones that do tend to be the proposals worth funding.

    If your AI program were a clinical program, what is its primary endpoint?

    If naming it is difficult, the program may still be worth running. It is not yet worth defending, and at some point this year someone will ask you to defend it.


    Sources

    MIT NANDA, “The GenAI Divide: State of AI in Business 2025,” July 2025.
    Coverage: Forbes, 26 Aug 2025.