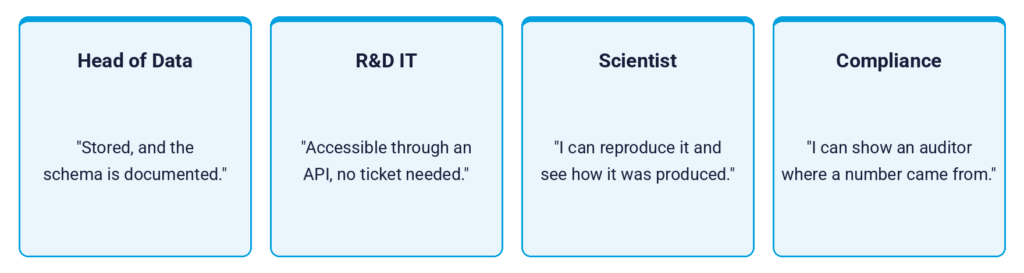
AI-ready is not a single property. It usually means at least four different things depending on who is asked: stored and documented, accessible without friction, reproducible by a scientist, or defensible to an auditor. Organizations get into trouble when they buy against one definition and are later judged against another.
A question with four correct answers
Every organization I talk to wants AI-ready data. I hear it in first meetings, in RFPs, in board decks. What I almost never hear is what ready means. And when I do receive a definition, it rarely survives the next person in the room.
Ask whether the data is AI-ready and the yes comes fast. Ask what ready means and you get the pause. I have sat through that pause enough times to know what follows: the same four answers, from four different chairs in the same meeting.
The same question, asked of four roles in one organization.
The head of data says it is in the warehouse and the schema is documented. R&D IT says accessible through an API without raising a ticket. A scientist says they can reproduce a result and see how it was produced. The compliance lead says they can show an auditor where a number came from and who changed it.
All four are correct. None of them is the same test.
Why the ambiguity is expensive
This is where it gets expensive, and I have watched it happen more than once. A company buys against one definition and gets judged eighteen months later against another. The tool did what it promised. The promise answered a question nobody had confirmed was the right one.
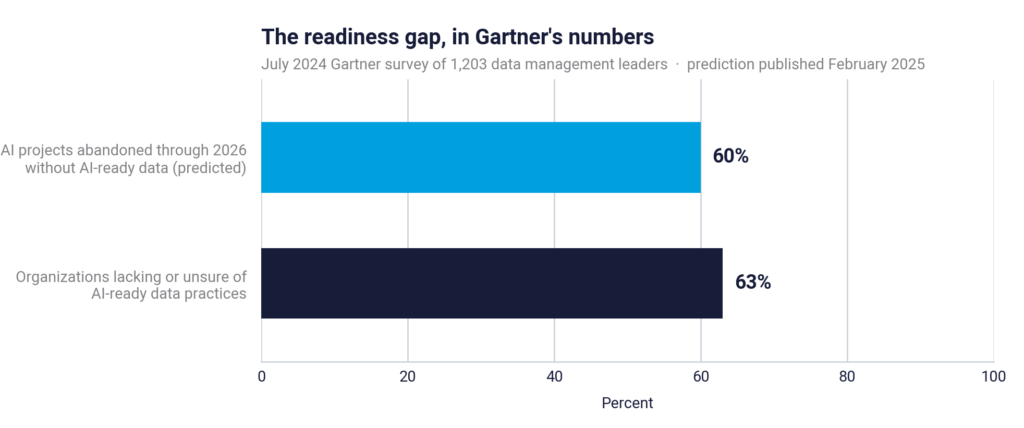
Gartner predicted that through 2026, 60% of AI projects unsupported by AI-ready data would be abandoned — a figure surveyed across industries, not pharma alone. My guess, and it is only a guess: a meaningful share of those projects involved data somebody inside the organization had already certified as ready. Certified against one of the four definitions. Abandoned against another.
The four definitions are not bought together
This is the part that catches even careful buyers. Findable does not mean reproducible. Accessible does not mean defensible. Each definition implies different work, different systems, different owners. A purchase that satisfies one can leave the other three exactly where they were.
None of the four is wrong. The mistake is treating them as one word.
What to do about it before the next evaluation
My advice is not glamorous. Ask the four people separately, in writing, before anyone drafts a requirements document. The disagreement is the requirements document. Finding it in a room costs an afternoon. Discovering it in year two costs the program.
The readiness question
If you asked four people on your team what AI-ready means, how many answers would you get?
If the answer is one, that is worth verifying rather than celebrating.
Sources
Gartner, “Lack of AI-Ready Data Puts AI Projects at Risk,” 26 February 2025.gartner.com Primary disclosure naming the analyst, survey period and sample size.
This is the written version of the talk I gave at Lab of the Future Europe in Amsterdam on 23 September 2026, in the AI to Innovate session. Sources, figure credits, and further reading are at the end.
Agents now do real scientific work, and the bottleneck has moved from what a model can do to what a team can check. Workflow grounding is DataJoint’s answer: agents read and extend the same declarations the work runs on, so every result traces to its inputs, its code, and the decisions behind it. A harness makes a model useful for one campaign. A formally defined workflow is what lets the work compound after the agents are gone.
The Lab of the Future Europe congress spent two days in Amsterdam on one question: what scientific work will look like when we make full use of automation and artificial intelligence to solve the hardest problems in medicine and life sciences. Automation, connected instruments, digital CMC, and AI running through all of it.
Instruments stream into shared stores instead of onto a workstation under the bench. Notebooks and inventory systems speak to each other. AI agents read a protocol, write the analysis for it, and call the tools to run it. In synthetic chemistry, propose–make–measure cycles close with nobody in the middle.
The possibilities feel intoxicating. Hand an agent a question and it proposes the work, runs what can be run against the data already in hand, and comes back with candidates ranked and its reasoning attached — for many questions at once.
At DataJoint we implement the scientific data foundation for research teams in pharmaceutical, clinical, and academic research. So the question we keep asking is whether the work compounds: does the group know more than it did, in a form the next question can use? That is a question about the workflow, not about the agents, and it gets harder to answer the longer the agents run before anybody asks it.
The bottleneck moved
Today, agents analyze the literature covering an entire domain. They propose and execute statistical analyses. They propose hypotheses, and they design experiments, protocols, and methods. It feels as though we should be able to solve problems that were out of reach, not only to work faster.
The progress has been rapid, and it has created new bottlenecks.
Ask a room of scientists what goes wrong when they work with capable agents, and the answer is almost never that the model was not clever enough. The most common complaint I hear is this: all I do is review what the AI produced, and I am behind.
Agents generate copious output that looks good. It reads as plausible, often as insightful and promising. And every so often there is an embarrassing, inexplicable mistake — the wrong data used, or two datasets silently mismatched.
That is the hard part. Errors you miss, inside work that looks right. How do we know which conclusions are trustworthy? And will we be able to defend them six months or a year from now?
Agents are wonderful brainstorming partners. Longer stretches of unattended work that lead to decisions need a much tighter level of rigor, and rigor is a property of the workflow rather than of the model.
How AI gets grounded
AI agents have improved in two ways: model capabilities and their grounding in the subject matter. Over three years the models gained larger context windows, better tuning, tool use, and reasoning they can explain.
The grounding is our ability to adapt a model to your subject matter, your questions, and your data. We have been through several rounds of this, each one tightening the grounding of an answer in the relevant data and making the answer easier to check against it.
Era
How knowledge is reached and checked
2021–23 · fine-tuning
absorbed into the weights — not checkable
2022–24 · prompting
pasted into the window — by reading it
2023–24 · retrieval
ranked passages — by following the citation
2025 · context engineering
assembled before the answer — by the context engineer
2025 · MCP
live query into your systems — by asking the system again
2026 · science harnesses
assembled per campaign — by the code and reasoning it records
now · workflow grounding
curated as the work runs — traced to inputs, code, decisions
The second column describes the checkability of the data used. A model weight cannot be asked where it came from. A citation points at a document but does not reproduce its derivation. A live query tells you what a system holds today, but not how it got there.
The newest of these is the science harness, a term now doing a lot of work in the field. A science harness is the environment built around a model that gives an agent tools, memory, compute, and a record of what it did.Kosmos, from Edison Scientific, and Claude Science, from Anthropic, are two of the best-known. They are serious engineering, and the record they keep is real evidence: it names what ran, on what, and when.
If we think of models as wild horses — strong, intelligent animals with minds of their own, entirely capable of acting destructively — then a harness is what lets them do useful work on the things you care about. But a harness is fitted to one horse for one race. What you also need is a track.
A track sets the lanes so that many horses can run at once, at full speed, with checkpoints along the way. And when you lay out a track, you make the straights long: long enough for an agent to do real work, to branch, to iterate on a design, and to come back with findings for a decision instead of questions along the way.
The earlier grounding methods wrapped around the model. They are model-centered approaches, and their aim is to maximize and showcase what a given model can do. A harness reaches your experimental data from the outside, and the one thing it cannot check is the thing you are judged on.
Workflow grounding
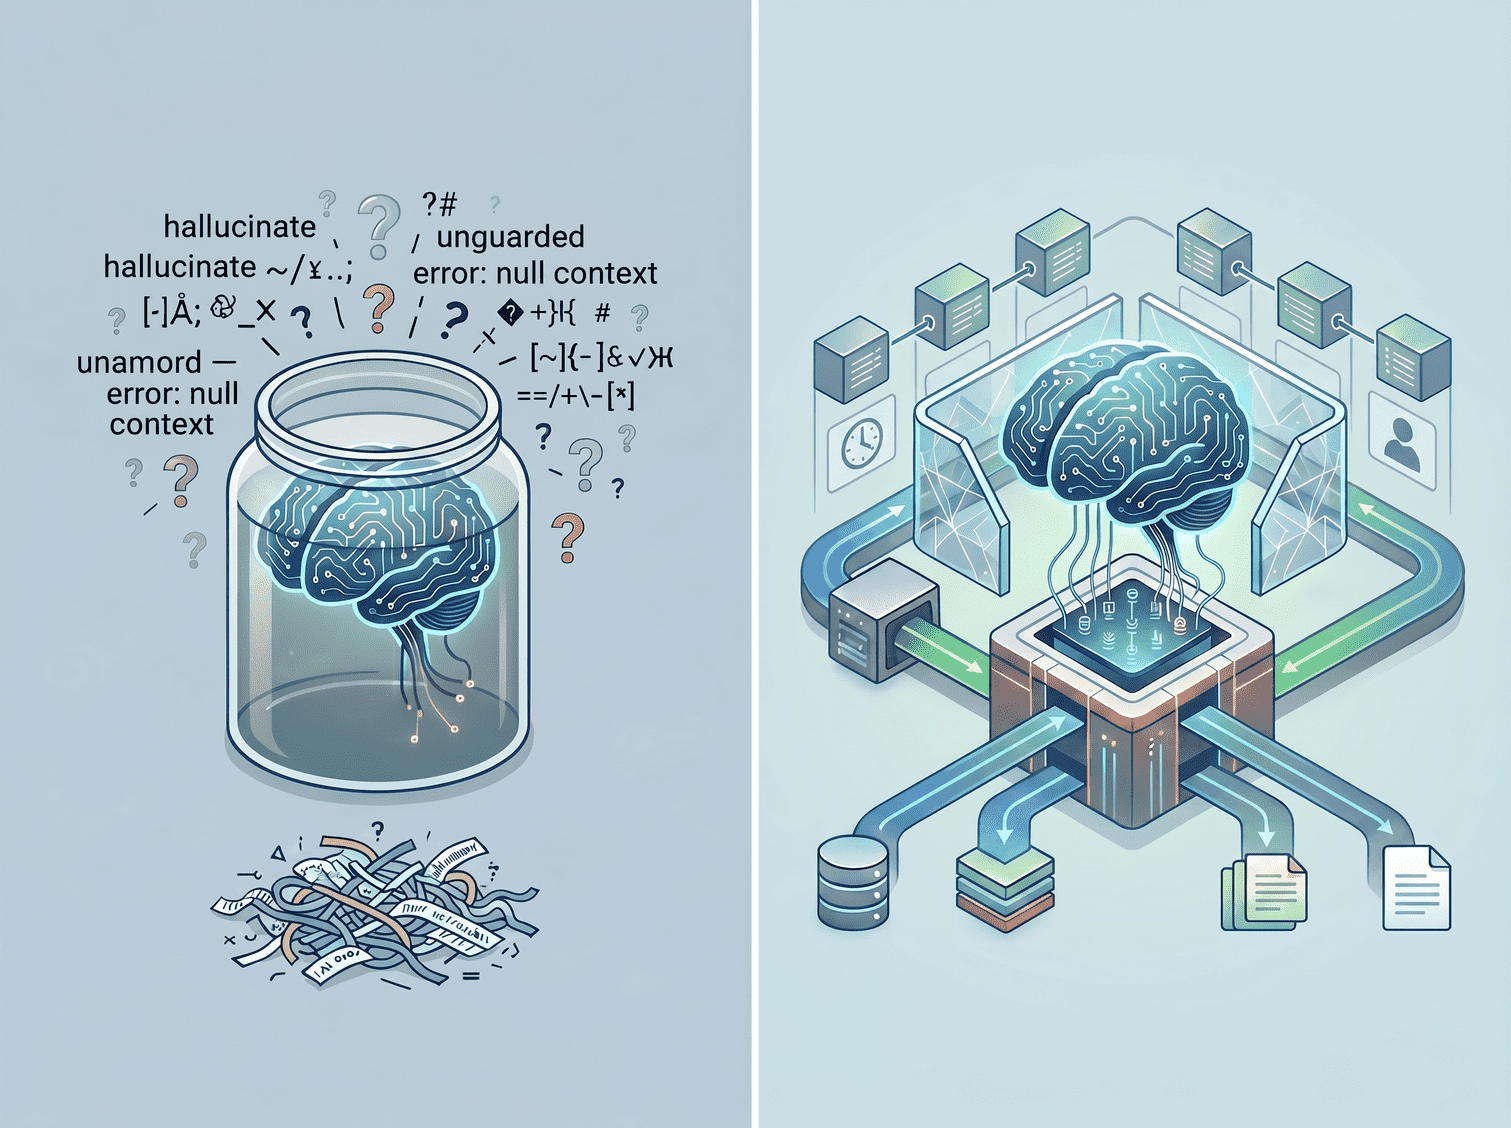
Workflow grounding starts from the other end: from the scientific workflow the lab actually performs. An agent is grounded in that workflow when it reads and extends the same declarations the work runs on — the entities, the dependencies between them, the code that produces each result, and the state of every derivation. The context is not assembled around the model; it is the workflow itself, and it outlasts the agent that used it. This is where much of the next few years of effort will go.
Other speakers at this congress described something close to it in their own words — multiagentic workspaces, and multi-agent orchestration as the layer that connects capabilities into coherent scientific workflows: the shared, persistent environment any number of agents plug into, defining the tools, the interfaces, the guardrails, and the rules for operation and record keeping. Different words, converging on the same conclusion: the durable object is the workflow, not the agent.
The self-driving-laboratory work arrives at it from synthetic chemistry rather than from data infrastructure: La Agente Óptima, from the Acceleration Consortium, separates the agent’s reasoning from the executed campaign and keeps a persistent optimization state between them, so that auditability follows from the architecture instead of from logging what the model said. (A survey of data agents published five days after this talk extends the term to a workflow harness, and lists among its open problems that what one run learns does not reach the next — which a harness cannot fix, because it dissolves with the run that used it.)
So how should we know whether any of this is working? Usually we measure how much faster we produce results with AI assistance. But the more important question is what is left at the end. After a year of such work, will you have a solid body of work that the next phase can build on? Or a year of copious documents that nobody — including you — can explain, defend, or reproduce?
It will not matter nearly as much how much work was produced, or how fast.
Precise notation lets knowledge compound
I have heard many people say that in 2026 the hottest programming language is plain English: whatever you can articulate clearly and precisely, your agent can deliver. There is something real in that, and there is a trap in it.
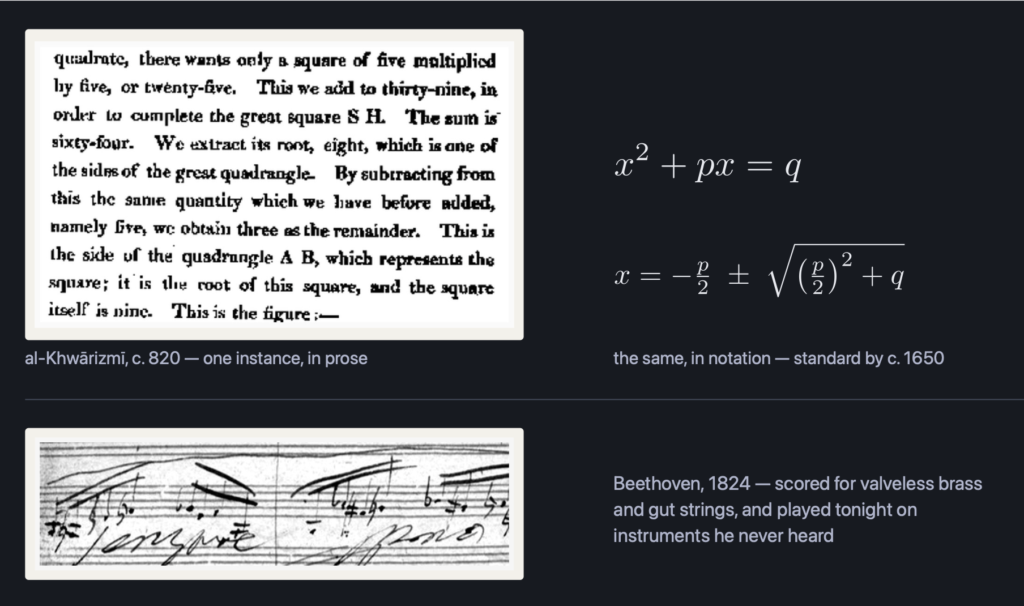
We may be living through a period much like how mathematics was done a thousand years ago. Arabic mathematicians in the Middle Ages could solve quadratic equations. But they did it, and taught it, in copious prose with diagrams. Here is a ninth-century solution to a quadratic equation, translated into English — about ninety words of correct reasoning that you can follow, and cannot transform.
Precise notation lets knowledge transform, compound, and be checked.
The notation that evolved over the following eight hundred years is far more than shorthand. It expanded our cognitive capacity to transform expressions and derive new results. The same equation now takes two lines, and schoolchildren learn it in every culture on earth.
Notation also makes work independent of the machinery that carries it. Music could not be expressed in prose. Before musical notation, music passed by ear from master to pupil — which is how a great many research teams still operate. Beethoven scored the Ninth in 1824 for valveless horns and trumpets, gut strings, and keyed wooden flutes. Within a generation of his death, valved brass was taking over from the horns and trumpets he wrote for, and tonight the same score is played on instruments he never heard. It never needed rewriting, because it specifies the music and not the machinery.
Research workflows need that same independence. The instrument is replaced, the cluster is decommissioned, the file format is superseded, the vendor is acquired — every one of them on a shorter cycle than the science. A workflow that exists only as the scripts that happen to run it expires with them. A workflow written in a formal notation moves, because what it specifies is the work rather than the machine that ran it.
Precise notation lets knowledge transform and compound.
Software has run this experiment too. In the 1960s and 70s it was thought that programming would become more accessible if programs read like English sentences, and that push produced COBOL and the fourth-generation languages. Computer scientists have since found algebraic notation the more potent form, and the English-like programming languages have faded. The exception is SQL, a relic of that era that survived because the vendors standardized it (ANSI in 1986, ISO in 1987), so a query written for one database runs on another with minor changes. People outside programming still use it every day: a formal language, scoped to one domain, that a person can read.
Notice where agentic AI has made its most impressive progress: exactly the domains that already had precise formal notation and verifiable results. Mathematics and programming. That is where a model can be trained against a verifiable answer under clear rules.
The same holds for research workflows. To invent a workflow, to transform it, and to judge whether it is any good, we need a way to express it precisely and formally — so that humans and machines both understand it unequivocally.
A formal language for research workflows
So what language do we use to express a research workflow and reason about it?
We already have several domain-specific languages, for data, for computation, for infrastructure, and for governance. A real workflow needs several of them at once, and each is correct inside its own scope.
Language
What it specifies, and what it leaves out
CWL, Nextflow, Snakemake
A directed acyclic graph of tasks with typed inputs and outputs — plainly, the steps and the order they run in. It leaves out the entities those steps produce: results are files the engine does not model, so nothing carries a result’s identity or its relation to the results on either side of it.
Terraform, Helm
A declarative target state for infrastructure, reconciled by a control loop — plainly, the machines and services, and what correct looks like. It leaves out the science: it can tell you a cluster is running, and nothing in it records what ran there.
Cedar, OPA
Authorization policy — principals, actions, resources, and conditions, evaluated per request; plainly, who may do what. It leaves out what the data is: a policy permits a read without saying what was read, or how that row came to exist.
dbt
SQL transformations with declared dependencies, materialized and tested inside a warehouse — plainly, how one table is built from other tables. It leaves out acquisition, instruments, computation that is not SQL, and work that is queued rather than done.
SQL DDL
Relations, domains, keys, and integrity constraints — plainly, the structure the database will hold. It leaves out how any of it came to be: derivation lives in code outside the schema, so a row cannot name what produced it.
Relational Workflow Model
Entities, their dependencies, the code on each, the constraints, and the state of every derivation, in one declaration carrying structure, dependency, and transformation together — plainly, the workflow itself, as a database that computes it. It leaves deployment and access control to the rows above, by design.
The lacks differ in detail and agree in kind: none of these languages carries the work itself. They describe a static structure, and scientific work is not static. It branches. It is rerun with a changed parameter. It is partly computed and partly waiting. In science, how a result was derived is the contract, and a specification that leaves derivation to an engine outside itself has left out the part that matters.
A traditional database records what happened. A computational database defines how it happens.
For this purpose we developed the Relational Workflow Model: a semantic refinement of the classical relational database that makes computational transformations a native part of the schema. It is the language for constructing and evolving a scientific data foundation, and we develop it as an open standard, so that projects built on it stay freely interchangeable.
The DataJoint library is the Apache-2.0 reference implementation. The argument for it as a formal language, worked through against a relational ERD of the same pipeline, is in Schema as Workflow Grammar.
The scientific data foundation
A formal way to express and transform workflows is what lets us define a data foundation in a real lab.
DataJoint provides the scientific data foundation where scientific work is codified as formally defined, self-executing workflows — free to evolve while their integrity, provenance, and reproducibility hold up by design — so that people and their AI agents can build on them with full trust.
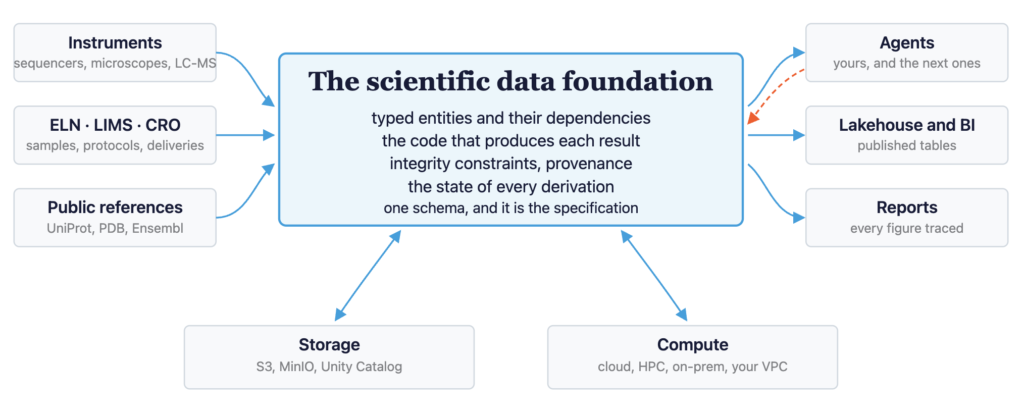
It holds the typed entities and the dependencies between them, the code that reproduces each result, the integrity constraints, and the state of every derivation. It does that as a relational schema, and the schema is the specification of the workflow.
And it fits the infrastructure you already have: the instruments, the systems of record, the lakehouse, the compute. Instruments keep acquiring and systems of record keep their records; what arrives lands against a declared entity. The bytes stay in the object store you already run, because what the foundation holds is the entity, its lineage, and the code that produced it, not the payload.
The orange path on the right of that diagram is the only arrow a machine does not cross by itself. Agents read the schema and the job state, and their changes come back as declarations a person merges.
Using this model, people and agents alike can understand, express, extend, and transform the workflow as the project evolves.
The operational cycle
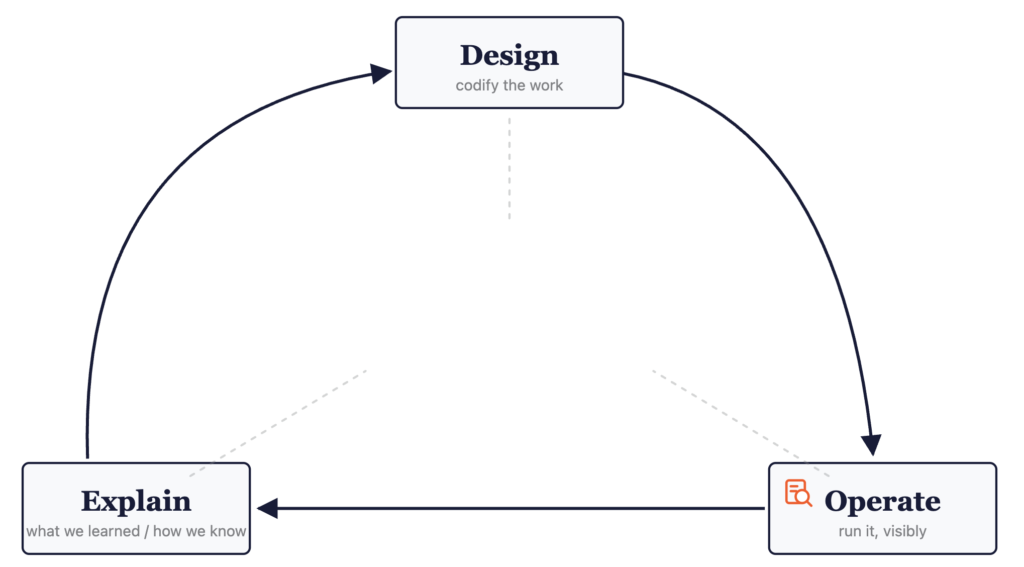
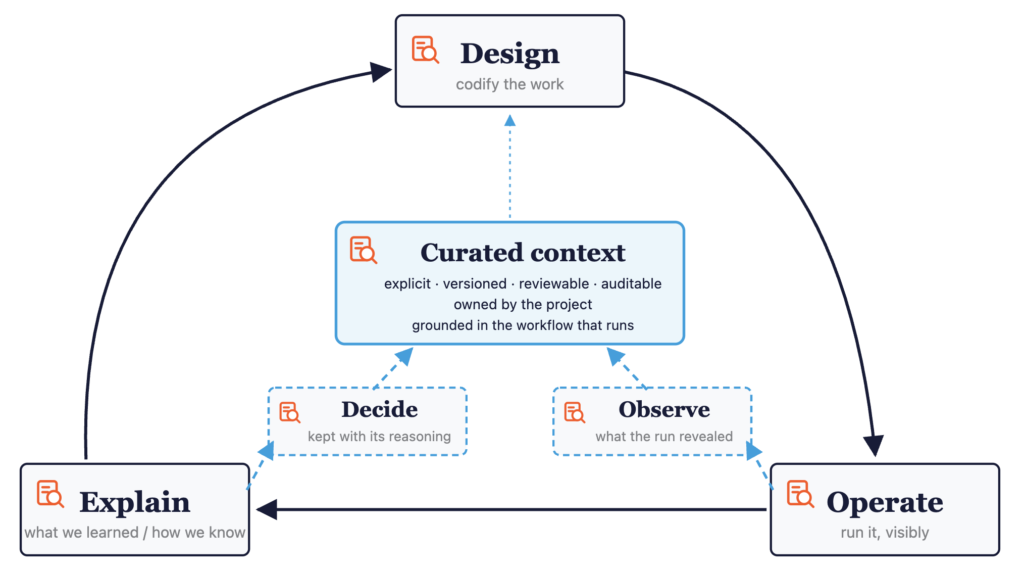
For the sake of this discussion, model scientific operations as a loop: you design the work, you operate it visibly, and you explain what you learned and how you know it.
Every group draws its own version of this loop, and nothing that follows depends on there being three acts.
Regulation has focused on the Operate side of this loop — that inputs and transformations are traced and the data well governed. That is why Operate is the one act carrying an audit mark. The loop works. It produced the medicines in current use.
What is not typically modeled or formalized is the context in the middle: the motivations and aims, the decisions, the observations. That happens in meetings, in emails, in conversations — and it is where a team’s knowledge accumulates. Just as with music before notation, it passes from master to pupil, between generations of researchers. It aggregates, but not in a form an agent can use to build the next question on.
Implementing the scientific data foundation lets us formalize the Design and Explain parts of the loop as well, so that every act becomes inspectable, auditable, and analyzable by humans and agents alike — not Operate alone.
But it also requires a process for a shared, managed, curated context. That context becomes the grounding for the research team and for the agents, and it is aggregated while the work happens rather than collated afterwards. Learning is branched, reviewed, and merged together with the workflow it belongs to — the git-based process, applied to what a project knows. Which means bringing that context out of the emails and the Zoom calls.
Observe and Decide were always happening anyway. Somebody always noticed what a run revealed; somebody always decided to stop or to go on. What is new is that both are written down, so they tighten the cycle instead of dispersing from it.
Each turn of the loop leaves the project knowing more than it did before.
This is what we are building at DataJoint: agents that contribute at every part of the loop, helping the team operate the cycle and aggregate the context while the work runs, rather than reanalyzing after the fact.
An example workflow
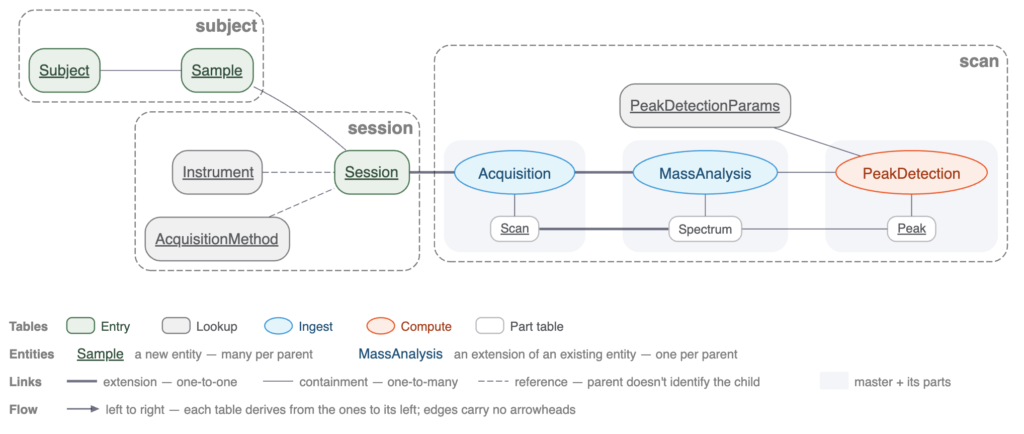
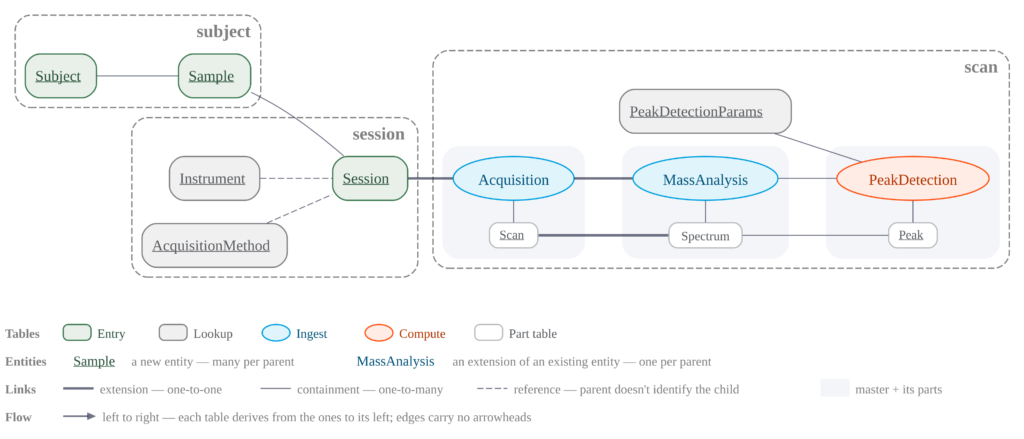
Here is a workflow expressed in the Relational Workflow Model. This is the schema diagram, where each node is a table representing a step.
The connections between nodes are foreign keys, and they establish both data integrity and execution order. Rows in those tables are the workflow artifacts produced at each step. Whereas a traditional database captures entities and the relationships between them, a workflow database defines and executes how the data is collected and transformed.
This one is liquid chromatography and mass spectrometry — twelve entities, public, and the same workhorse in discovery, in bioanalysis, and in QC, so the shape of it travels. It is at once a relational database and an executable workflow: data entered by hand or from the electronic laboratory notebook, parameters in lookup tables, ingestion recorded, computations logged and versioned. Each node is a snippet of Python that declares the data structure, the dependencies, the order of operations, and the transformation the step performs — one construct doing three jobs, which is why they cannot fall out of agreement. Computation is part of the schema definition, not something bolted on beside it. And the figure was not drawn: it is generated from the pipeline it describes, so it cannot drift from it.
One story about this pipeline. It is the exemplary design in our own preprint — and when we asked an agent to review it against our own design checklist, it found defects. A table linked to its upstream by a comment saying the keys matched, rather than by a foreign key that would enforce it. This made us both proud and embarrassed — an agent we coached outperformed our own reasoning. It is fixed now, in the public repository. And we expect this to become a virtuous cycle: improvements inform new improvements, applied automatically.
With a formal representation of the workflow, agents become remarkably effective at designing, evaluating, and operating research workflows — and, as on this pipeline, they begin to catch what the original authors missed, on exactly the dimensions we care most about: quality and rigor.
A production pipeline at Johns Hopkins
DataJoint was first battle-tested in neuroscience mega-projects. The MICrONS project characterized the structure and function of a cubic millimeter of mouse visual cortex — some 75,000 neurons imaged in the awake animal, and an electron-microscopy reconstruction of more than 200,000 cells and half a billion synapses — and DataJoint was the backbone of the shared neurophysiology component from 2016 to publication. The results filled a Nature special issue in April 2025; our own account of the pipeline underneath them is A Better Data Engine for Brain Science.
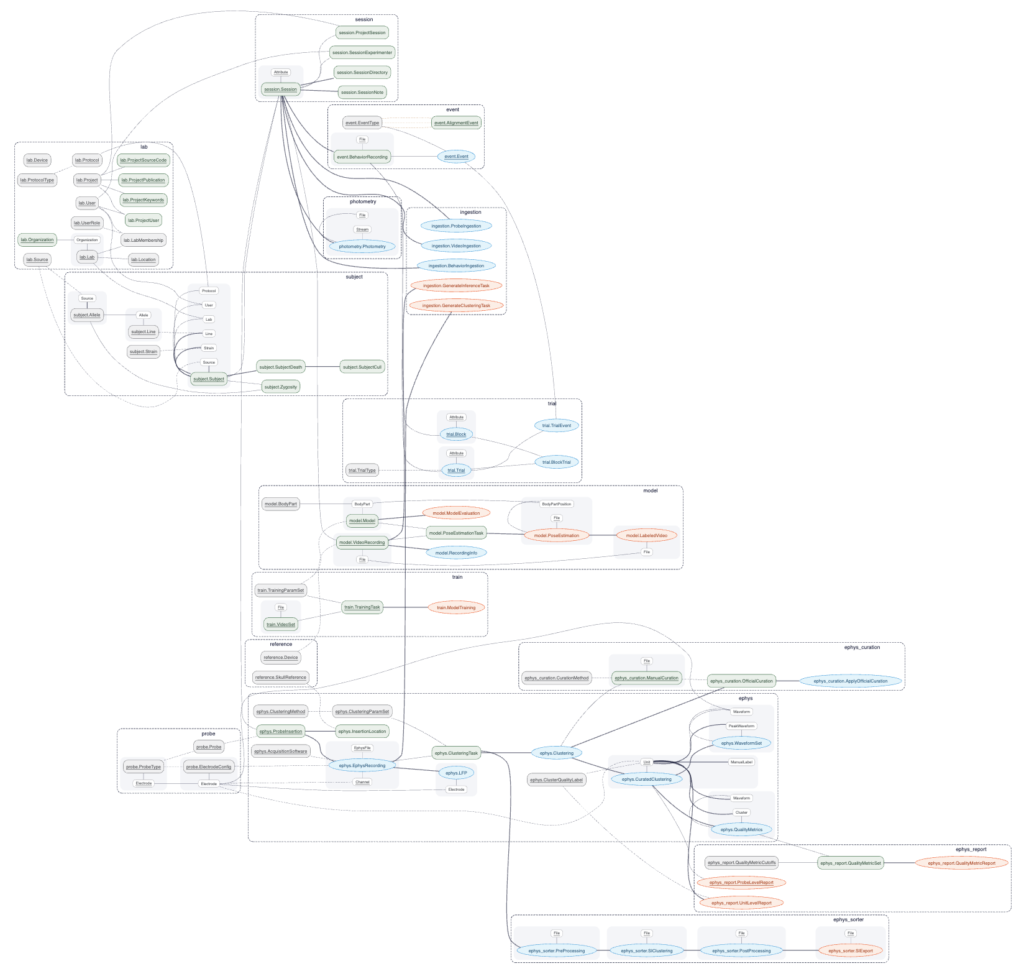
The pipeline below is from the Shuler Lab at Johns Hopkins — subject and colony management, photometry, electrophysiology with GPU computation, running in production for years.
The first thing the picture buys is that the whole operation is one legible object. Manual entry, acquisition, heavy computation, and reporting sit in one graph, so a question about any result is answered from the structure rather than from whoever happened to run it.
The second thing is that the schema follows the lab’s own code. When the code in their repository changes, the structure extends with it, so code and schema move together instead of drifting apart. Marshall Hussain Shuler, quoted in our April 2025 Nature Research Custom feature: “We have already saved months and ran experiments that we never could before.” Two different units in one sentence — months saved is throughput, and experiments that were not previously possible is feasibility, which no hourly rate prices.
Zoom into the electrophysiology chain and you can see the grain of it: the recording as it came off the probe, a clustering task carrying its parameter set, the clustering itself, and curation as its own declared step. Methods and their parameters are entities in their own right, not arguments buried in a script. So the pipeline keeps evolving as the lab takes on variations of the experiment: change a setting, run it again, and you get a second result beside the first rather than one that quietly replaced it.
Later in the pipeline the work becomes analysis, reports, and figures — and figures are computed through the same dependencies as everything else. A figure is normally the least governed thing a laboratory produces: made in a notebook, exported, pasted into a deck, and from that moment disconnected from the analysis it summarized. Here, recomputing the analysis recomputes the figure with it. A figure in a deck is an orphan, and in a regulated laboratory an orphan is an audit finding.
Trustworthy AI is achieved by distrusting AI
So how do we defend what we learn, when much of the work is proposed and performed automatically? Workflow grounding lets us turn agents loose on many things at once, which makes that question sharper.
Trustworthy has a technical definition now: the ability to meet stakeholders’ expectations in a verifiable way. That is ISO’s wording, in ISO/IEC TS 5723:2022, and the EU AI Act uses the same term. Verifiable — not persuasive, not well-documented, not confident.
Regulators on both sides of the Atlantic have written the same requirement into law and guidance. In the EU, the AI Act — Regulation (EU) 2024/1689 — names trustworthy AI as its purpose in Article 1, and for high-risk systems it requires automatic logging across the system’s lifetime (Article 12), information sufficient for a deployer to interpret the output (Article 13), and human oversight by people who can understand what the system did (Article 14).
Those high-risk obligations were then deferred by the Digital Omnibus on AI, Regulation (EU) 2026/1744, in force since 27 July 2026 — to December 2027 for stand-alone Annex III systems, and to August 2028 for AI embedded in regulated products — while the Article 50 transparency duties took effect on schedule in August 2026. The date moved; the requirement did not.
Read them together and the same requirement appears in each: a record that lets someone else check the work. Not one of them asks whether the output was impressive.
And so trustworthy AI is achieved by distrusting AI — by making it show its work, and by making that work inspectable and verifiable. Verifiability, curation, and accountability follow.
Verifiability. A claim can be checked instead of believed, because the derivation behind it is recorded as structure and not as narrative.
Curation. The context is explicit, versioned, and owned by the project, rather than accumulated inside an agent’s memory. Agents come and go; the workflow and the curated context are what endure. If a new agent — or a human researcher — cannot reproduce the work from that context, the work is not finished. We do not forbid agents that remember. We refuse to depend on implicit memories.
Accountability. Agents can run long stretches autonomously, and people decide at checkpoints. Workflow grounding is what defines those stretches: an agent loops on a branch of the workflow, and at the end of the stretch its work is verified before it is merged. A checkpoint is not a rubber stamp — the accountable person has to understand what actually happened. And in each of these frameworks, it is the human scientists who are held accountable, because they have skin in the game. The AI co-scientist, well, has no skin.
None of that caps how much runs unattended. The gates sit on the consequential calls, and everything between them belongs to the agent. Explicit, inspectable aggregation is what makes agents faster, not what slows them down.
Ground for the next agents
Agents are fast and powerful, and we should assume they are ephemeral. Ground them in a workflow that is formally defined and written in one schema, and rigor holds while the agents run at speed.
This approach takes work. What it buys is work that aggregates and compounds — which is also what your regulators and your own quality people will ask you for.
AI agents will keep becoming more capable, and they cannot be the entire difference. The difference is what the operational cycle accumulates. The work in front of us is to ground the workflow, so that knowledge accumulates while the work runs.
The ideal agent is the one you never see. The ideal process lets the scientist see the science itself most clearly: what a decision implies, and what an experiment actually revealed.
What are your agents standing on, and where does their work go?
References and figure credits
Lab of the Future Europe 2026, Beurs van Berlage, Amsterdam, 22–23 September 2026 — lab-of-the-future.com/europe. The talk this piece is adapted from was given in the AI to Innovate session on 23 September.
How to Accelerate Research with AI Scientists and Multi-Agent Orchestration — Rob Brown, Sapio Sciences, Lab of the Future Europe, 22 September 2026. The published agenda describes multi-agent orchestration as the layer that connects these capabilities into coherent scientific workflows — a formulation close to the shared environment this essay calls workflow grounding.
Yatsenko, D., et al. DataJoint 2.0: The Relational Workflow Model. Preprint — arXiv:2602.16585. The formal definition of the model, its query algebra, and the substrate elements built on it.
Schema as Workflow Grammar, DataJoint, 12 August 2026 — datajoint.com/news/schema-as-workflow-grammar. The formal-language argument, worked against a relational ERD of the same pipeline.
ISO/IEC TS 5723:2022, Trustworthiness — Vocabulary, July 2022 — iso.org/standard/81608.html. The source of the definition of trustworthy used above: the ability to meet stakeholders’ expectations in a verifiable way.
Regulation (EU) 2024/1689, the AI Act, in force 1 August 2024 — eur-lex.europa.eu. Art. 1 (human-centric and trustworthy AI as the stated purpose), Art. 12 (record-keeping), Art. 13 (transparency and provision of information to deployers), Art. 14 (human oversight) for high-risk systems.
Regulation (EU) 2026/1744, the Digital Omnibus on AI, published 24 July 2026 and in force 27 July 2026 — eur-lex.europa.eu. Defers the high-risk obligations to 2 December 2027 for stand-alone Annex III systems and to 2 August 2028 for AI embedded in regulated products; the Art. 50 transparency duties applied from 2 August 2026, with a four-month grace period on the Art. 50(2) marking obligation for systems already on the market, ending 2 December 2026.
NIST AI 100-1, Artificial Intelligence Risk Management Framework (AI RMF 1.0), 26 January 2023 — nist.gov/itl/ai-risk-management-framework, doi:10.6028/NIST.AI.100-1. The seven characteristics of trustworthy AI, including accountable and transparent and explainable and interpretable.
FDA, Considerations for the Use of Artificial Intelligence to Support Regulatory Decision-Making for Drug and Biological Products, draft guidance, January 2025 — fda.gov. A risk-based credibility assessment framework for an AI model in a stated context of use.
MICrONS Consortium, Functional connectomics spanning multiple areas of mouse visual cortex, Nature640, 435–447, 9 April 2025 — doi:10.1038/s41586-025-08790-w. The flagship paper of the April 2025 Nature special issue, The MICrONS Project. DataJoint was the data backbone of the neurophysiology component, selected in 2016.
A Better Data Engine for Brain Science, DataJoint, 22 April 2025 — datajoint.com/news/better-data-engine-for-brain-science. Our own account of the MICrONS pipeline and the labs that followed it — republished, slightly expanded, from the Nature Research Custom two-pager of April 2025, which is the source of the Marshall Hussain Shuler quotation in A production pipeline at Johns Hopkins (the two-pager as printed).
Müller, M., Bai, J., Gottstein, W., et al. La Agente Óptima: Towards Agentic Self-Driving Laboratories, 3 September 2026 — arXiv:2609.04564. LLM reasoning separated from the executed campaign, with a persistent optimization state between them, so that control returns to the agent only when progress needs interpretation. Evaluated on two physical platforms, including a five-day flow-chemistry campaign that raised yield from 30% to 59% over 23 experiments. Presented at this congress by Willi Gottstein of the Acceleration Consortium, in the Orchestrated Lab track on 22 September.
Kosmos: An AI Scientist for Autonomous Discovery, Edison Scientific, November 2025 — announcement, arXiv:2511.02824. A structured world model as the agents’ shared memory, assembled per run and dissolved with it: up to twelve hours, some 200 rollouts and 1,500 papers, every conclusion cited to code or to literature.
Zhou, H., Zhang, Y., Du, J., et al. Towards Reliable AI Data Scientists: Data Agents with Workflow Harnesses, 28 September 2026 — arXiv:2609.35255. Published five days after the talk, and cited here in the note above rather than in its argument. A survey organizing LLM data agents around five stages — perception, planning, execution, verification, repair — under what it calls the workflow harness, “the control structure that governs how this trajectory is constructed, monitored, and revised.” Its diagnosis matches the one above: “silent failures can persist even when individual components function correctly.” Two of its four open reliability problems — missing experience transfer, and the missing verification-repair repository — are the case for a durable object outside the run.
Claude Science, an AI workbench for scientists, Anthropic, 30 June 2026 — anthropic.com. Curated connectors to public reference databases, jobs submitted to the lab’s own HPC cluster over SSH, and an auditable history — exact code, environment, and message history — on every output.
Figures: the operational-cycle pair, the foundation in context, and the notation composite are adapted from the Lab of the Future deck; the LC-MS schema and the Shuler Lab pipeline are dj.Diagram output generated from the schema definitions in each pipeline’s public code repository; neither diagram draws on any data. The al-Khwārizmī plate is from Rosen’s 1831 translation of the Algebra and the Beethoven plate from the autograph of the Ninth; both are public domain.
THE SHORT ANSWER: The gap is whether the work can travel
Pharma R&D organizations share nearly identical AI ambitions, and the spending now matches the ambition. The gap is not strategy or talent. It is whether the work underneath can travel: whether a result can be rerun by someone who did not produce it, and whether a pilot that succeeded in one lab can move to the next.
Identical ambitions, identical budgets
I spend a lot of my week talking with pharma executives, and the ambitions have converged. Everyone wants the same four things.
Accelerate discovery.
Shorten development timelines.
Put AI in the hands of scientists.
Do it without adding risk.
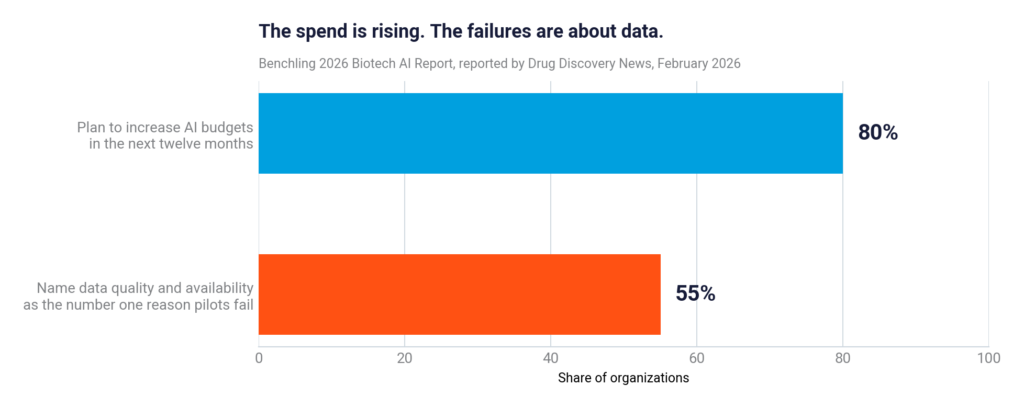
The spending now matches the ambition. In Benchling’s 2026 Biotech AI Report, a survey of biopharma organizations reported by Drug Discovery News in February 2026, 80% of organizations plan to increase their AI budgets in the next twelve months.
Read that number the way I did. If nearly everyone has the same goals, and nearly everyone is raising spend, then neither goals nor spend will decide who wins. Something else will, and it is the one thing that never appears in a strategy deck: where each company is starting from.
Two companies, same strategy
Here is the contrast I keep running into. One company spent six years making every result rerunnable before it bought a single AI license. Another is modernizing in flight, with thirty active programs depending on the systems being replaced. Both call themselves AI-forward. Both are telling the truth.
But ask each one what a new hire would need to reproduce last year’s most important result. Only one has an answer.
Neither the goals nor the budgets will decide who wins. The starting line will.
The gap shows up eighteen months later
The gap never shows up in the pilot. Pilots are run by motivated people with the builder one desk away. It shows up eighteen months later, when the work has to travel: to another team, another site, or simply to next year.
The same report puts a number on why: 55% of organizations name data quality and availability as the number one reason AI pilots fail. Not model choice. Not talent. The condition of the scientific work underneath, and that condition was set years before anyone approved an AI budget.
Benchling 2026 Biotech AI Report, reported by Drug Discovery News, February 2026.
Preparation is quiet, and it decides the outcome
I have never seen any of it in a press release. Consistent data models. Provenance captured as the work happens, not rebuilt afterward. Workflows that produce the same answer twice. Quiet work. And it decides whether an AI investment compounds or evaporates.
The question to take into your next AI review
If this program had to move to another team or another site tomorrow, what would break first?
Whatever you name is the starting line. Not the strategy, not the budget. The thing you just named.
THE SHORT ANSWER: Most R&D organizations preserve their data and lose their reasoning. The measurements survive; why a target was dropped or a protocol changed usually does not. AI exposes the gap immediately, because a model can summarize what was kept and cannot recover what was never captured.
Data survives. Reasoning does not.
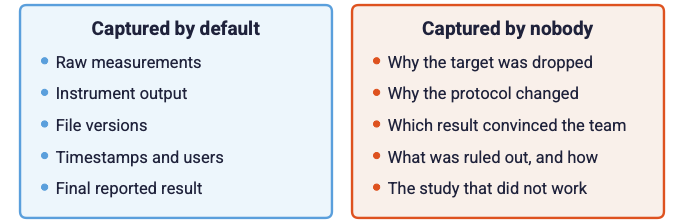
Most R&D organizations I speak with do not have a data shortage. Storage is cheap, instruments are prolific, and the measurements are almost always there somewhere.
What is missing is why. Why a target was dropped in 2023. Why an assay protocol changed between two campaigns. Which result convinced a team to move forward, and which one told them to stop.
What a typical R&D record retains, and what it does not.
The pattern repeats across organizations of every size: the compound history is in the system, and the decision history is in a few people’s heads. By the time anyone goes looking, one of them has usually left.
AI makes the gap visible immediately
This was survivable when the person who ran the work was the person who explained it. AI removes that arrangement. Ask a model why a program was killed and you will usually get an answer, fluently, assembled from whatever documents happen to have survived.
A fluent answer is not the same as a true answer.
The output is not obviously wrong, which is the problem. A plausible account built from a partial record arrives with the same confidence as a retrieved fact, and nothing in the answer tells you which one you got.
The negative result is the costliest thing you are not keeping
In discovery, the study that did not work is the least likely to be written up with its full context, the least likely to be reviewed, and the first to be forgotten when the person who ran it moves on.
It is also the result that narrows the search space for everyone who comes after. The principle I keep coming back to:
No result should be wasted, including the ones that failed.
Every negative result that is not preserved is a study somebody else will run again, at full cost, to reach the same conclusion.
The economics of this are documented. In PLOS Biology, Freedman, Cockburn and Simcoe estimated that more than half of US preclinical research cannot be reproduced, at a cost of roughly $28 billion a year in the United States alone.
Their breakdown of causes:
biological reagents and reference materials at 36%
study design at 28%
data analysis and reporting at 25%
laboratory protocols at 11%.
More than a third of the problem traces to how work is analyzed, reported and documented, not to the materials or the design.
The same paper notes that the underlying biases can result in entire studies never being published or reported at all. The negative result does not just lose its context. It disappears.
A recollection is not a record
Some organizations try to close the gap afterward: exit interviews before a scientist leaves, retrospective write-ups, a wiki that nobody maintains past the second quarter. Reasoning captured afterward is a different artifact. It is a recollection, which is useful and is not the same as a record.
A record is made at the moment of the decision, by the people inside it, with the alternatives still on the table. A recollection is what someone believes happened, filtered through everything that came after, including how it turned out.
That is why this does not fix itself later. The reasons get captured as the work happens, or they get approximated afterward. And an approximation is exactly what a model will treat as ground truth.
The question to take into your next AI review
Where does your organization keep its reasons, and who could find them without asking a person?
The second half of that question is the one that matters. If the answer is a person, the reasoning is not stored. It is borrowed, on terms that end when they do.
Sources
Freedman LP, Cockburn IM, Simcoe TS, “The Economics of Reproducibility in Preclinical Research,” PLOS Biology 13(6), 9 June 2015. journals.plos.org
Science, “Study claims $28 billion a year spent on irreproducible biomedical research,” 9 June 2015.science.org
THE SHORT ANSWER: A year ago, pharma R&D leaders evaluated AI by asking about the model. Now they ask whether a recommendation can still be supported six months after it is made. That shift explains why so many AI programs stall. The model was rarely the constraint. The systems underneath were never built to answer the second question.
The question used to be about the model
A year ago, most AI conversations in pharma R&D opened the same way. Which model? How large? Trained on what? The technology was new enough to be the subject.
That has changed faster than almost anything I have seen in this industry. In the portfolio reviews and steering committees I hear about now, the model barely comes up. What comes up is what happens afterward.
The top-20 pharma leaders I interact with have converged on what I believe is the more important question:
If we pursue a particular AI strategy, can we support our reasoning six months from now?
Not at the demo. Six months out, when a program decision is examined by a partner, a regulator, or whoever inherits the work. Not because the models failed. Because nobody could fully stand behind the output.
Why the shift is happening now
The timing is not a coincidence. Enough programs have reached the point where early AI decisions carry consequences, and the people who made them have moved on.
Gartner put numbers on the gap in February 2025. A July 2024 survey of 1,203 data management leaders found that 63% of organizations either lack the right data management practices for AI or are unsure whether they have them. On that basis, Gartner predicted that through 2026, organizations would abandon 60% of AI projects unsupported by AI-ready data.
Read the prediction carefully, because the wording carries the argument. It does not say the models underperform. It says projects get abandoned, which is a different kind of failure. Somebody could not stand behind the output when it mattered.
And abandonment is no longer hypothetical.S&P Global’s Voice of the Enterprise: AI & Machine Learning, Use Cases 2025 survey of 1,006 IT and line-of-business professionals across North America and Europe found the share of companies abandoning most of their AI initiatives before they reach production rose from 17% to 42% year over year, with an average of 46% of projects scrapped between proof of concept and broad adoption.
What walking it back involves
The question sounds simple until a team tries it. Take one AI-informed recommendation from last quarter and follow it backwards.
There are five steps.
Name the exact version of the code that produced the figure.
Retrieve the inputs as they existed then, not as they exist now.
Rerun it. Same number?
Show what changed in between, and who changed it.
Find the context that turned that number into a decision.
Most organizations manage the first two steps in an afternoon and stall on the third. Almost none reach the last one, because the context was never written down anywhere that outlives the person who did the thinking.
These are risk questions, not model questions
Can we explain how the recommendation was reached? Can we rerun it and get the same answer? Can we scale it without scaling our exposure? None of those are answered by choosing a better model, and all of them are being asked of leaders who inherited an AI budget without inheriting the systems underneath it.
That is an uncomfortable position, and it is where a lot of R&D leadership currently sits. The mandate arrived first. The foundation it depends on was built for an earlier era, when the person who ran the analysis was also the person who explained it; and was still down the hall when the questions came.
What the organizations making progress have in common
It is not budget. The teams I see making steady progress are rarely the ones spending the most. What they share is a decision made early, before anyone was watching:
That trust, governance, scientific rigor and full context are foundational rather than paperwork arranged around the real work.
That decision costs real money in year one and compounds in value every year after. It rarely appears in a strategy deck. Leaders make it quietly, and the results speak later.
The question to take into your next AI review
Which AI-informed decision from last quarter could you walk back to the raw data today, step by step?
If the answer takes more than an afternoon to establish, that is the finding. Not a failure of the model, and not a reason to slow down. It is a measure of the distance between where your AI program is and where it will need to be six months from now.
Sources
Gartner, “Lack of AI-Ready Data Puts AI Projects at Risk,” 26 February 2025.gartner.com Primary disclosure naming the analyst, survey period and sample size. Both figures appear verbatim.
S&P Global Market Intelligence, Voice of the Enterprise 2025. spgglobal.com The primary source: a survey of 1,006 midlevel and senior IT and line-of-business professionals across North America and Europe. Both figures appear in S&P’s own wording.
Run “data integrity,” “data consistency,” “data governance,” and “data provenance” through Google’s Ngram corpus, and ask when each of them entered use.
The four terms arrive in order. Integrity comes first, rising from the 1970s — the decade the relational model arrived — and dominating the vocabulary for the next four decades. Consistency follows in the 1980s and settles early at a modest level, where it stays. Governance and provenance don’t launch until the mid-2000s. Then governance climbs steeply enough to very nearly catch integrity by 2022, while provenance lifts only faintly: in the most recent data it still trails integrity by a factor of eight.
The relational model accounts for that gap. Codd and fifty years of database research talk about integrity and almost never about provenance, because the model solved the problem at a deeper level. Provenance became a named discipline in the 2000s in workflow and e-science computing (Buneman 2001; the W3C PROV working group from 2011), where the substrate could not enforce relationships between artifacts. If your results are files produced by scripts, nothing stops you from holding a result whose inputs are gone. So you keep a record beside the data describing what happened, and you work hard to keep that record honest.
Provenance is the complete record of a data entity’s origin: what produced it, from what inputs, under what conditions, and through what chain of transformations.
Customers routinely expect that definition to cover two things it leaves out: the scientist’s reasoning, and governance.
Provenance records the how, and stops short of the why. The standards ask who, when, and by what means, and so does 21 CFR Part 11. Someone who asks for provenance and means “capture why the scientist chose this analysis” is asking for a different system. Say so early.
Governance is the wider regime — access, cataloging, audit, retention — and provenance is one component of it. DataJoint produces the authoritative provenance that a governance system consumes.
The literature also splits provenance into prospective, the declared plan, and retrospective, the observed run (Freire 2008; Lim 2010). Integrity is preventive. Provenance tooling is forensic. Prevention and forensics are different guarantees, and much of the confusion in this field comes from buying one and assuming the other.sic. Prevention and forensics are different guarantees, and much of the confusion in this field comes from buying one and assuming the other.
The Standards Landscape
Three families of systems account for most of what the field means by provenance tooling. They are also how the rest of the world will phrase its questions.
W3C PROV is the vocabulary: Entities (a thing), Activities (something acting on entities over time), Agents (who bears responsibility), joined by relations like used, wasGeneratedBy, wasDerivedFrom, and wasAttributedTo.
Figure: the PROV core types and relations, from the W3C PROV Primer (W3C Working GroupNote, 30 April 2013), reproduced under the W3C Document License.
OpenLineage is the same shape recast for data engineering — runs of jobs that read and write datasets — and it is the lingua franca of Airflow, Spark, and Marquez. Governance catalogs — Unity Catalog, Collibra, Alation, Purview, DataHub — record table and column lineage across the enterprise.
Then there is compliance, which is where pharma actually lives. ALCOA+ — attributable, legible, contemporaneous, original, accurate, plus complete, consistent, enduring, available — and 21 CFR Part 11, with audit trails that no one, administrators included, is permitted to delete. ALCOA+ is defined in PIC/S PI 041-1 and in the UK MHRA’s GXP data integrity guidance; Part 11 is 21 CFR Part 11, Electronic Records; Electronic Signatures. These are obligations of a deployment and a process, never features of a library.
In genomics the same shape appears again in the workflow standards of the Global Alliance for Genomics and Health (GA4GH), and in data science in the run-metadata stores that record inputs, parameters, and outputs for each run.
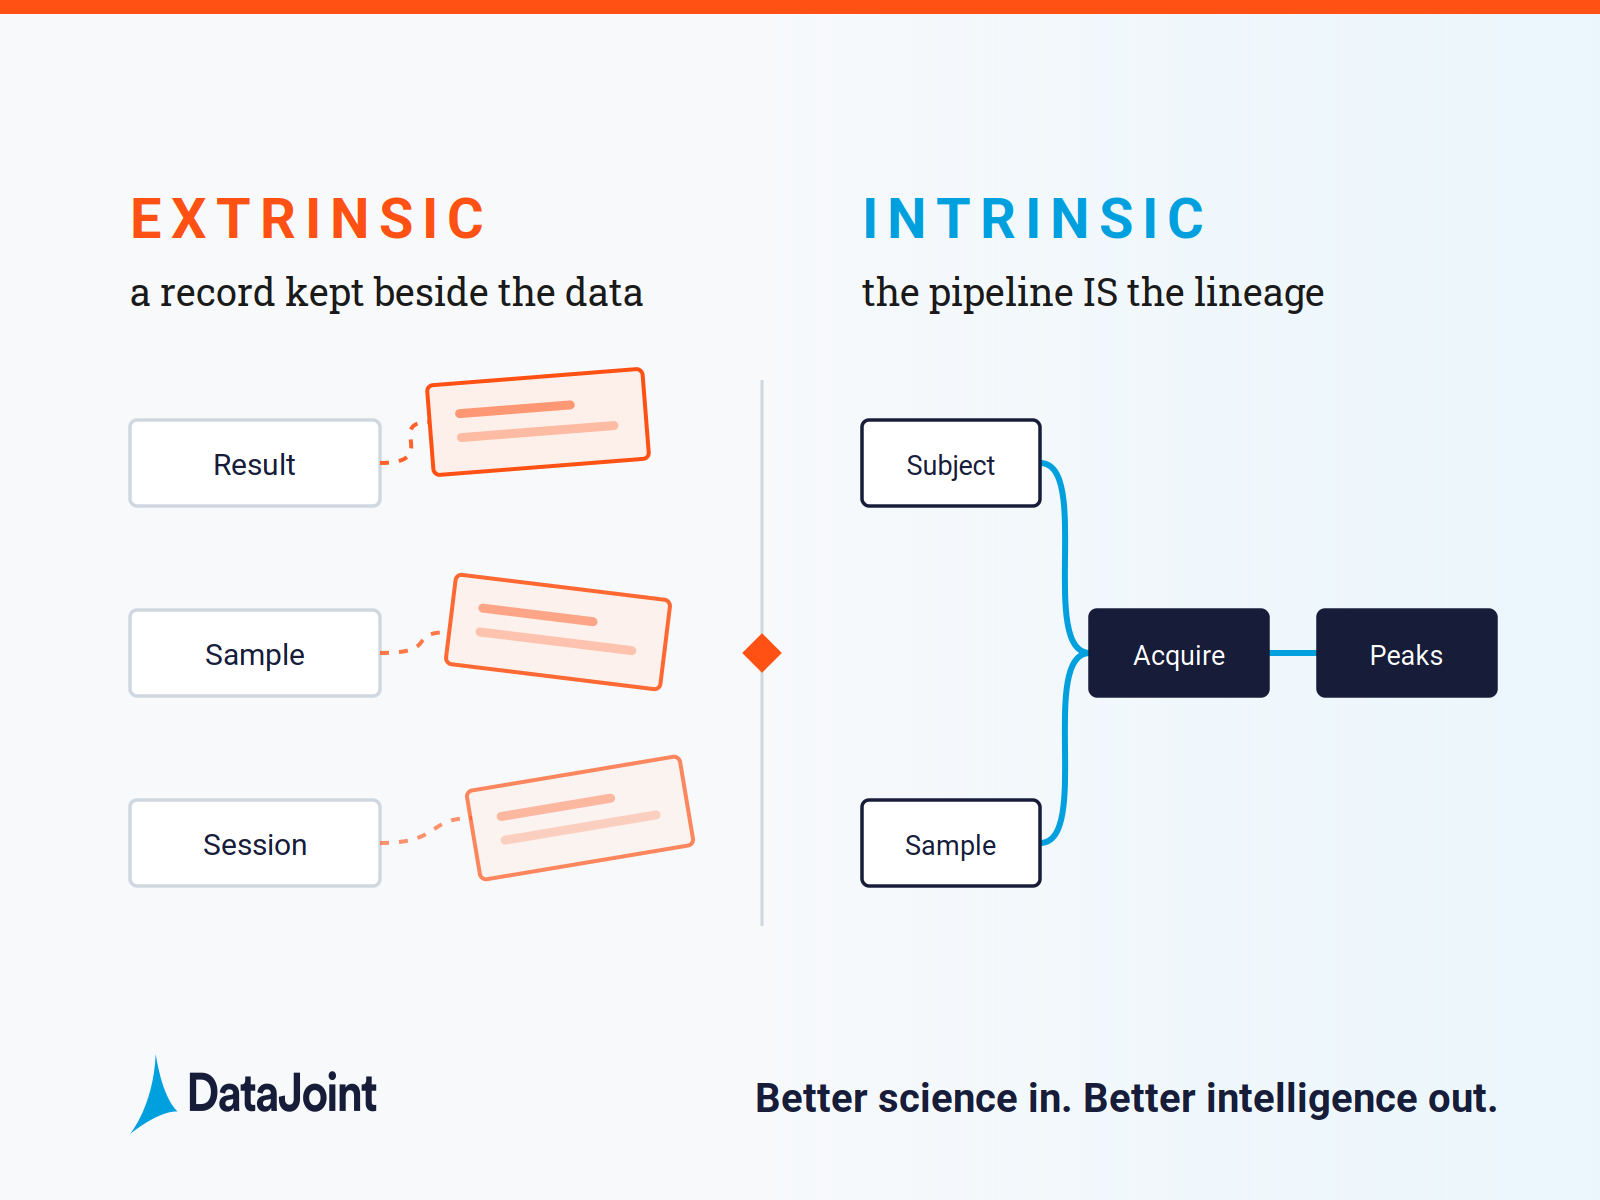
What every one of these families has in common is that the record is kept beside the data. Keeping it there is the only option available when the substrate cannot do better. The consequence is that there are now two things to keep in agreement, and nothing but diligence keeps them there.
One Slice Each
Three approaches cover most of what pharma runs today, and each covers its slice well. Document versioning tracks records rather than computation: version every controlled document, with no computational lineage underneath it. That is the quality and regulatory world, where Veeva Vault is the de facto standard. Metadata cataloging renders enterprise lineage as a graph, as Collibra and Informatica do; it traces, it does not enforce. Domain audit logging captures every edit with user, timestamp, and reason inside one boundary, which is what Medidata Rave does for electronic data capture in clinical trials. Large internal integration platforms move research data at enormous scale, with provenance supplied by whatever tooling sits on top of them.
Each covers one slice, well. None makes provenance a property of the data itself. The provenance system and the data system are separate systems, and separate systems can diverge.
How the ELN and the Workflow Fit Together
The system a bench scientist actually touches is the electronic lab notebook (ELN): Signals Notebook across most of large pharma, Benchling across much of the adjacent market. It is where the provenance chain starts, and the two systems fit together at that seam. The notebook attests to what was done at the bench. The workflow carries what was computed from it.
Every generation of the notebook, from paper through the AI-assisted tools now arriving, rests on the same mechanism: an experiment is recorded, and a second person reviews it and signs.
That signature is provenance of a specific kind: attestation. A named person asserts that the work was done as described, which is what ALCOA+ codifies and why contemporaneous is on that list. Recorded as the work happens, not reconstructed afterward. It is the right instrument for the bench, where what has to be vouched for is human judgment and physical work. It says someone vouched. It does not say the result could not have been otherwise.
Vince Paton, who spent years selling these systems, draws the line: “An ELN captures the experiment, DataJoint captures the science.” The notebook is authoritative for what a person did at the bench. The workflow is authoritative for what was computed from it. Neither is trying to be the other, and the two kinds of assurance compose: attestation at the boundary, structure downstream of it.
So the integration is a join, not a migration. The notebook’s entry identifiers and sign-off enter the workflow as the extrinsic record on the rows they describe — source, agent, time — and every result computed from those rows carries that identity in its lineage. Ask where a figure came from and the chain runs from the result, through the computation that produced it, back to the signed notebook entry it began in.
The join has to work by reference rather than by copy, and that is the practical requirement customers state themselves. Pointing an ELN’s search at a lakehouse or an object store would mean replicating that data into its backend, which they decline to do. Nothing needs replicating. The ELN keeps its record, the workflow keeps its structure, and the provenance chain crosses the boundary intact.
Two Pictures: Assembled vs Declared
Compare what each approach actually produces.
First, from the W3C PROV Primer, the complete provenance graph for one newspaper article: every entity, activity, agent, and relation needed to describe how a single artifact came to be.
Figure: the complete provenance graph for the Primer’s worked example, from the W3C PROV Primer §5, reproduced under the W3C Document License.
It is assembled by observation, it is stored next to the thing it describes, and keeping it accurate is somebody’s job.
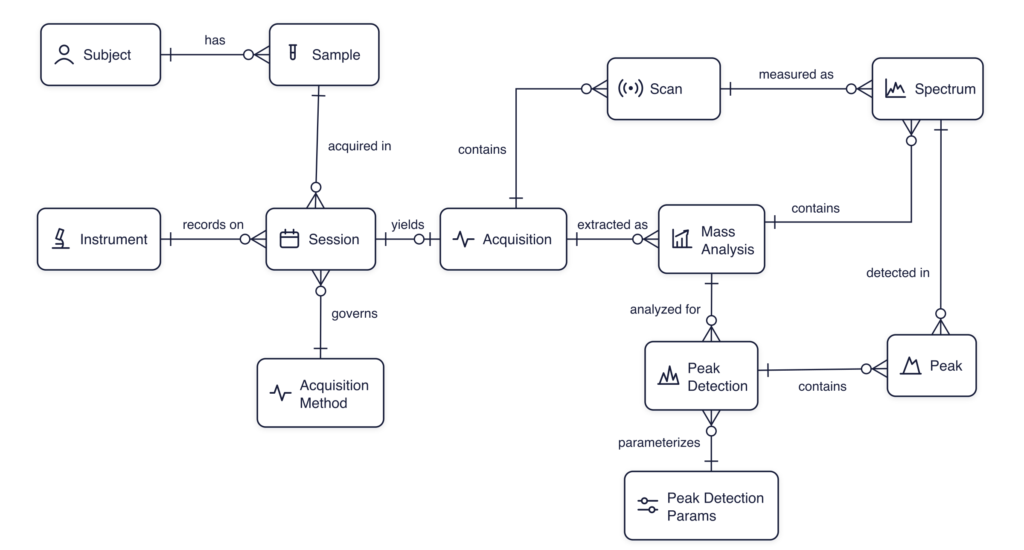
Now the schema of a liquid chromatography–mass spectrometry (LC-MS) workflow: twelve entities and their parts, dependencies running left to right, origins carried by shape and color.
That one diagram is the lineage of every row in every table. Nobody assembled it. It was declared before any data existed, and the database refuses to hold a computed result whose upstream dependencies are not present and correct.
A catalog can disagree with the data it describes; a schema can’t.
Why can a catalog drift when a schema cannot? Because the two artifacts in the second picture — the data and its lineage — are not two artifacts. They are the same one.
Provenance: Extrinsic vs Intrinsic
This is the distinction the rest of the vocabulary hangs from.
Extrinsic
Intrinsic
Source of guarantee
Observational: recorded as metadata
Structural: entailed by the data model
Posture
Forensic, after the fact
Preventive, before the fact
Failure mode
Can be incomplete, or drift
Cannot be created broken
Answers
“This datum was reported to come from there”
“This result must derive from these inputs”
As used here the terms are specific to the Relational Workflow Model, the model DataJoint introduces, formally defined in Yatsenko & Nguyen 2026. That is the definition this essay argues from. Intrinsic means entailed by the schema and enforced by referential integrity, not merely inherent in some general sense.
Extrinsic provenance is a record captured about data whose origin lies outside the model’s structural guarantees: read from an instrument, transcribed from a notebook, pulled from a laboratory information management system or a sample registry. Every system in the preceding sections produces this kind, and produces it well. Intrinsic provenance is entailed by the structure of the Relational Workflow Model and maintained by the database itself. It is not a record kept about the data. It is the data model.
Mapped onto the literature: extrinsic corresponds to retrospective provenance, intrinsic to prospective, with one sharpening. In DataJoint the prospective structure is enforced by referential integrity, so it is a binding guarantee rather than a declared intention.
The pair of terms came to DataJoint from Doug Welsh, in February 2026, from the commercial side rather than the engineering one and new enough to still hear the vocabulary the way a customer hears it. Two claims were sharing one word: customers who said they already had provenance had a careful record of what had happened, and DataJoint was offering something that is not a record at all.
The available reading was that DataJoint keeps a better record than the alternatives. He took the harder one: that it keeps no record, and the guarantee comes from somewhere else.
That reading was available to him because he had spent a career selling the alternatives: data virtualization into pharmaceutical accounts, the data lake and its catalog, unified storage, array stores for scientific data. Every one of those systems keeps a record about data it does not control, which is the extrinsic model sold for a living.
Part of that career was in declarative infrastructure. Infrastructure-as-code rests on the claim that a declaration is the source of truth and not a description of one, and that drift from it is worth building machinery to prevent. A schema that is the lineage is the same claim, moved from infrastructure to scientific data.
Naming the two kinds apart let each be judged on its own terms — the record for how faithfully it is kept, the structure for what it makes impossible. Doug had already made the underlying argument in print, that deterministic provenance has to be a property of the system that produces results, not a record kept alongside it. Naming the two kinds is what made that property easy to see.
“What struck me is how elegant it is. A result can’t exist unless its inputs are there — the provenance falls out of how the pipeline works. I spent a career around records kept next to the data, and that’s what got me: the science comes out more reliable because of how the system is built, not because someone remembered to document it.”
Doug Welsh, Chief Revenue Officer, DataJoint
Both kinds do necessary work. Extrinsic governs a workflow’s boundaries; intrinsic governs what happens inside it. A complete account needs both, joined at interfaces you can point at.
Origin, Contract, Code
DataJoint’s contribution is that the code for a computational transformation is part of the schema. A computed table’s declaration includes the make() that populates it. So classic data integrity comes to subsume computation. The problem provenance was invented to solve, reconnecting a result with the code and inputs that produced it, does not arise as separate bookkeeping, because the data and the transformation were never separated.
Three structural facts follow about every entity: where it came from, what code produced it, and whether it reproduces.
DataJoint marks every table by its origin. Each declaration states where the table’s rows come from, and that marking is the provenance classification. The four names answer one question — what puts rows in this table — which is the question provenance asks. Lookup — the code itself, via contents, so governed by code provenance: which committed version defined it. Entry — something outside the table: a scientist recording a study design, a sample registered on receipt, an instrument’s run sheet. The intrinsic chain begins here, and this is where the extrinsic record has to be captured, because the source is outside what the workflow tracks. Ingest — the table’s own make(), reading an instrument export or an upstream system the workflow does not control: an extrinsic boundary despite being automated. Compute — the table’s own make(), deriving entirely from declared upstream: fully intrinsic and reproducible.
The two nouns are tables somebody else fills. The two verbs are what populate() does. That split is the intrinsic/extrinsic boundary written into the names.
The marking has to match reality. A table filled through a form at run time is an Entry table however it is declared, because code provenance cannot vouch for what a person typed after the code shipped.
Determinism is the make() contract, five rules now published as part of the framework’s documentation (the make() contract, specified in full with rationale and enforcement model in the AutoPopulate reference §4.3):
Populate-only. Rows arrive only through make() via populate(), never a direct insert.
One entity per call, in isolation. One make(key) produces one master row and its parts. No shared state, no ordering, no reading peer rows, which makes populate embarrassingly parallel and each entity’s provenance self-contained.
Read only upstream, restricted to the job. Fetch only declared ancestors reachable from the key. The violation is not “an undeclared table.” It is reading outside the cone.
Write the result to self and its parts, atomically. Writes elsewhere are allowed, provided each destination is given its own extrinsic record.
No other result-affecting input. Arguments to populate orchestrate: batching, parallelism, logging. Anything that changes what is computed enters through a declared upstream table.
A rule you can point at is a rule a reviewer can check, and eventually one a tool can check. As unwritten convention, none of the five was either.
Code provenance is the third pillar, and it is routinely confused with the industry’s software provenance — software bills of materials, supply-chain attestation frameworks such as SLSA, in-toto — which certifies where a software artifact came from and who built it. Code provenance is process provenance in the PROV sense: the code is the activity that produced a data entity, and the record of which version of it ran. The deployment requirement is that populate runs from committed code whose dependencies the repository captures, so that a repo hash is a sufficient representation of what ran. Populating from an uncommitted working tree breaks it. repo hash is a sufficient representation of what ran. Populating from an uncommitted working tree breaks it.
Fan-Out at the Boundary
Fan-out is the established pattern for capturing provenance at the edge of a workflow.
An ingestion table’s make() reads one instrument export — an assay plate read, a chromatography run, a sequencing batch — and, besides its own result, inserts rows into the Entry tables that export describes: the subject, the sample, the session, each carrying the record of where it came from: the source, the agent, the time, and by what means. No foreign key points back to the table that wrote them, and none is needed, because the extrinsic record is the provenance. The contract allows exactly this. A make() may write beyond itself provided it supplies extrinsic provenance to each destination.
The reason the pattern exists is that the workflow changes what it is keyed by at this point. Before ingestion it is keyed by the vehicle that delivered the data: a file, an export, a dataset. After it, entities are extracted and the rest of the workflow is keyed by them: subjects, samples, sessions. The chain leaves the foreign-key graph and re-enters it, so the boundary write is where the account of the outside world gets attached.
The record rides on the destination row rather than in a log beside it, so it cannot be separated from the entity it describes. Only the master carries it; parts inherit it.
The framework produces intrinsic provenance automatically. Supplying extrinsic provenance is the workflow developer’s contract. Even when the source offers little — a nightly pull from a sample-inventory system, say — the author still records what arrived and when. The framework cannot infer what it did not compute.
Where Each Guarantee Is Enforced
The two kinds of provenance are enforced at two different times, and the split follows from what each one depends on.
Intrinsic provenance is settled at schema definition time. The lineage is structural, so whether it holds is a property of the declaration — and a declaration can be checked before it is allowed to define anything. A schema and its transformations are code in a repository: they pass through continuous integration, every branch is read statically, and deployment is pinned to the commit that passed. A transformation that would read outside its declared inputs never deploys, so it never produces a result to audit. This is prevention, and it is available precisely because nothing about it depends on a particular run.
Extrinsic provenance is enforced at run time, because that is when the outside world shows up. What instrument produced this file, which system it came from, who entered it, when it arrived — none of that exists at deploy time, and no static check can supply it. What the deployment can do is refuse to let it go unrecorded: the boundary write carries its source record as the data lands, and a write that arrives without one is not a tolerated gap but a failed ingestion.
So the platform holds both ends. Integrity is guaranteed before anything runs, by admitting only declarations that hold up — the familiar shape of infrastructure-as-code governance, applied to scientific workflows. The account of the outside world is captured as it enters, at the boundary, on the row it describes. Neither can substitute for the other: a static check cannot know what an instrument did last night, and a run-time record cannot make a badly declared workflow consistent.
The stakes rise as agents do the work. An agent produces results faster than anyone can read the record of them, so provenance that depends on being audited falls behind as a matter of arithmetic. What holds at that speed is the guarantee enforced before the run: a result that cannot exist unless its inputs do needs no reader to be true.
Export as Projection
Export is a projection, not a reimplementation. The lineage already exists, complete and consistent; export serializes it into a vocabulary someone else speaks. A row is a PROV Entity, a make() is an Activity, upstream reads are used, and the transitive closure of that upstream trace is wasDerivedFrom. OpenLineage takes the same content in run-centric form, which is how Unity Catalog, Collibra, and DataHub will read it. ALCOA+ maps line by line. Knowledge graphs are the general case, of which a provenance graph is one subgraph.
The mapping is total across the structural core and reaches as far as the deployment records. An auditor verifies the structure itself rather than a record kept beside it.
The data model is the lineage, and it cannot drift from the data, because it is the same thing as the data. That is what it means to sit upstream of the platforms an organization already runs: not another record of the science, but the structure the science is written in.
Integrity first. Provenance follows.
Better science in. Better intelligence out.
References and Figure Credits
Cited in the text:
Codd, E. F. (1970). A relational model of data for large shared data banks. Communications of the ACM, 13(6), 377–387. doi:10.1145/362384.362685
Buneman, P., Khanna, S., & Tan, W.-C. (2001). Why and where: A characterization of data provenance. Database Theory — ICDT 2001, Lecture Notes in Computer Science, 316–330. doi:10.1007/3-540-44503-X_20
Freire, J., Koop, D., Santos, E., & Silva, C. T. (2008). Provenance for computational tasks: A survey. Computing in Science & Engineering, 10(3), 11–21. doi:10.1109/MCSE.2008.79
Lim, C., Lu, S., Chebotko, A., & Fotouhi, F. (2010). Prospective and retrospective provenance collection in scientific workflow environments. 2010 IEEE International Conference on Services Computing, 449–456. doi:10.1109/SCC.2010.18
Moreau, L., & Groth, P. (eds.) (2013). PROV-Overview and PROV Primer. W3C Working Group Notes, 30 April 2013.
Yatsenko, D., & Nguyen, T. T. (2026). DataJoint 2.0: A computational substrate for agentic scientific workflows. arXiv. doi:10.48550/arXiv.2602.16585 — the formal definition of the Relational Workflow Model.
OpenLineage specification. LF AI & Data Foundation.
On the term: “intrinsic provenance” is also used, independently and without a shared definition, in artifact authentication — evidence recovered from an artifact’s own material properties rather than from an attached label (Sun, B., Trustworthy provenance for physical and digital artifacts with commodity mobile devices, National University of Singapore, extended abstract). The sense defined above is narrower and belongs to the Relational Workflow Model.
Figures:
Ngram chart — generated from the Google Books Ngram JSON API (en corpus, smoothing 3).
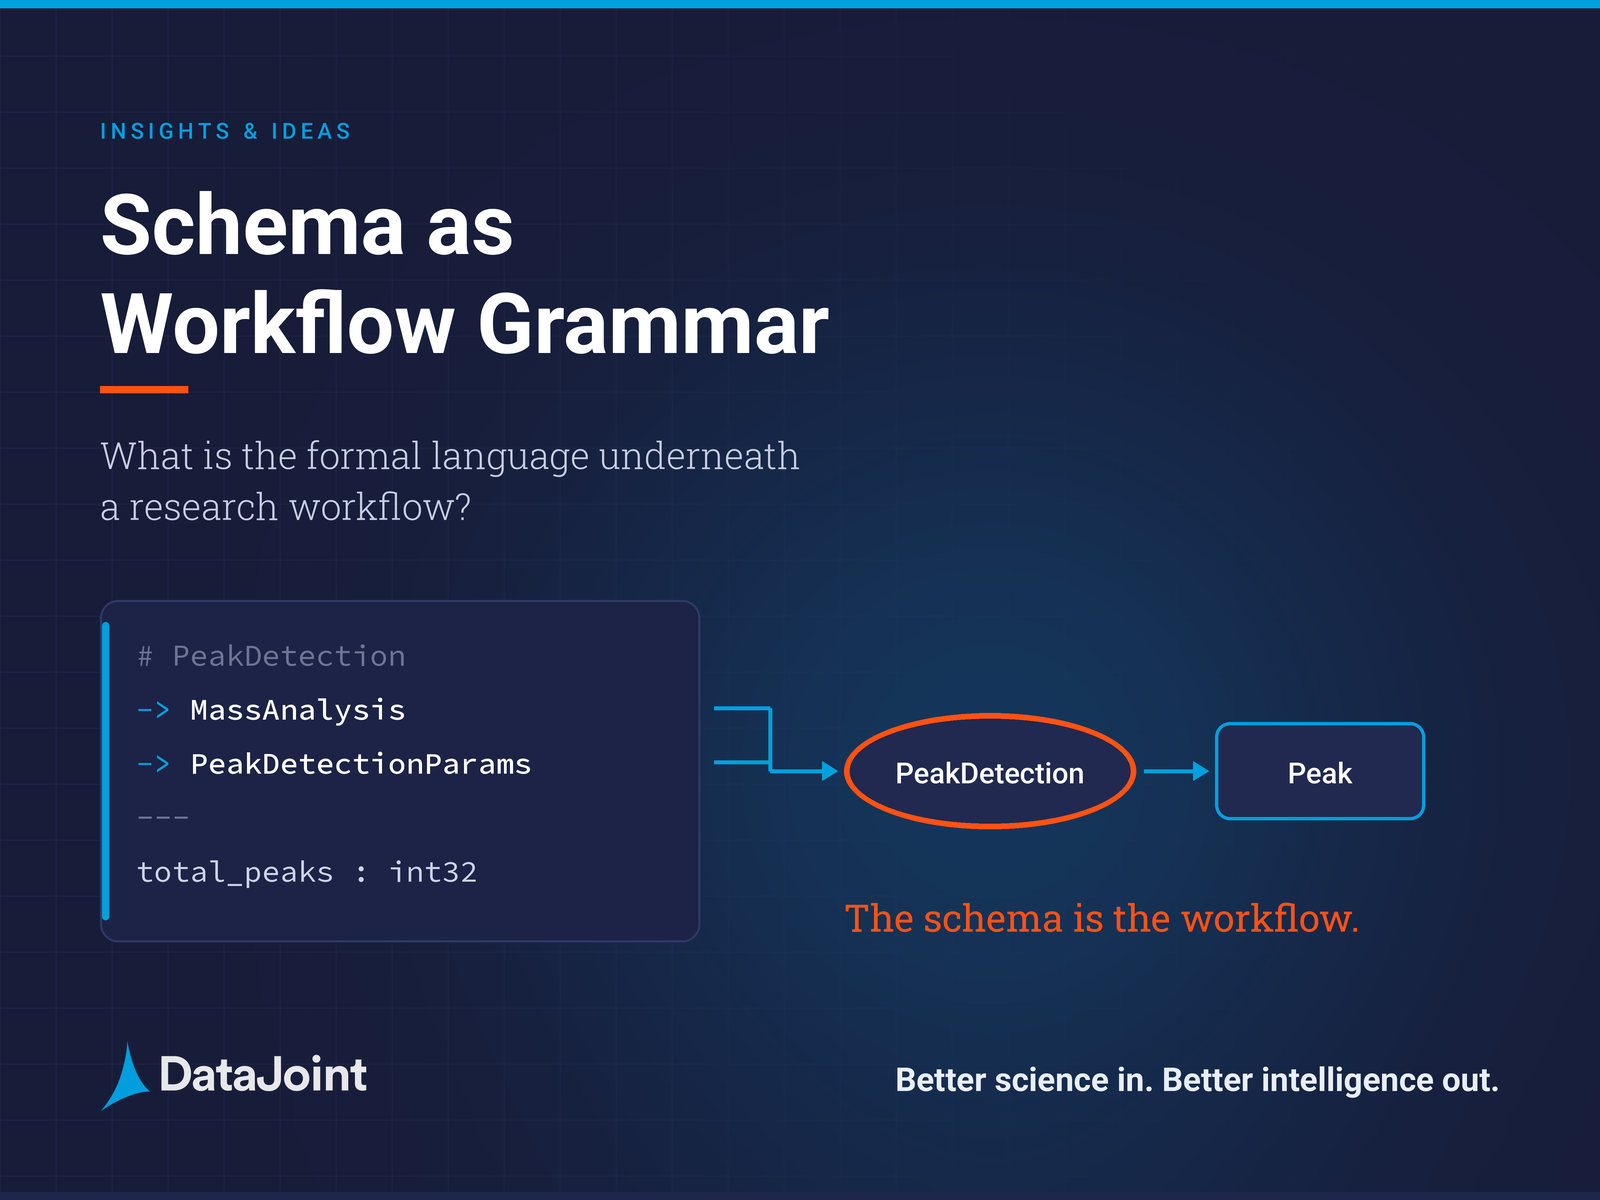
In DataJoint, the schema is the workflow. Not a description of the data after it lands, but a formal, executable specification of the process that produces it: tables are the steps, foreign keys are the dependency graph, and each derived table carries the code that computes it. That specification has a name — the Relational Workflow Model — and it answers the question infrastructure architects put to every system they are asked to trust: what is the formal language underneath? What follows is the case for it.
A new class of scientific harnesses arrived in 2025 and 2026. Systems like Edison Scientific’s Kosmos and Anthropic’s Claude Science give AI agents the tools, memory, and guardrails to run long, auditable research campaigns. Each of them had to build or assume a data substrate to stand on. Each drew its boundary just above the researcher’s own experimental data. That is where DataJoint sits: upstream, in the governed foundation where the lab’s own data and workflows live — where scientists and their agents reason over the same model of the science, and where reproducibility, provenance, and trust are properties of the foundation rather than artifacts assembled after the fact. Which raises the question this piece takes up: what is the formal language for the workflows at the heart of that foundation?
The question
What formal language describes a research workflow — the entities, the dependencies among them, and the chain of transformations that turns raw experimental output into a scientific result?
Twenty-eight minutes into a recent conversation with a senior pharma infrastructure architect, he stopped and asked it directly: “What language do we use to describe the process?”
He listed the comparators he had in mind:
YAML, for network configuration
Terraform, for cloud infrastructure
Helm, for Kubernetes packaging
Ansible, for config-drift management
Cedar, Amazon’s policy language, for authorization rules
Each is declarative. Each is formal enough that tools can parse it, reason over it, and exchange it. Each became a small standard in its corner of the stack because someone wrote down the spec, and others adopted it.
“If you can define the language or find one that you like,” he said, “that becomes a way to pull it up. I could feed that into anything. I could feed that into an LLM. Now I have written the control plane for where I’m going to use RAG and where I’m going to use context.”
The instinct underneath the question is correct, and it is the same instinct that produces every generation of durable infrastructure: a formal language is what survives the next platform shift. The tools come and go. The spec is what gets standardized, interchanged, and built upon.
So he asked: what is the formal spec for the scientific work DataJoint is recording?
One natural answer is “it’s codified in Python,” and it is a good one: it points to where the schema actually gets written. His question was aiming a level deeper, though. “Python is not a formal spec,” he added. “That’s just a programming language.” Exactly right, and it sharpens the question to its real form: what is the formal spec that Python is a binding to?
The answer to that sharper question was already written down in the DataJoint 2.0 paper (Yatsenko & Nguyen 2026).
What “schema” has meant
DataJoint’s core innovation is that the schema is the workflow: the proven principles of relational database design, refined and augmented to make computation first-class in the data model. To see what that adds, it helps to recall what a schema has meant until now.
The word schema is a database term of art. In Edgar F. Codd’s 1970 relational model, a schema is the formal description of stored data: typed columns, primary keys, foreign keys, integrity constraints. Peter Chen’s 1976 entity-relationship model added a conceptual model above that — entities, attributes, and the relationships between them, expressed at the modeling tier before the table layout is fixed. Both formalisms specify what the data looks like once it has landed. Neither specifies how it got there.
The transformation that produced the data has classically lived elsewhere — in application code, ETL scripts, workflow files, ingestion services. The schema describes the resting state; the production process is somewhere else, recorded (if at all) in logs and filenames after the fact.
DataJoint’s revision is one declarative move. The transformation is part of the schema. A make() method attached to each derived (Computed or Imported) table specifies how an entity in that table gets produced — invoked once per tuple in the join of the upstream tables referenced by its foreign keys. The transformation carries the same formal weight as the type of the column it produces. The schema is no longer a description of what exists. It is a specification of how a result comes into being.
This is the move that lets a schema serve as a workflow grammar — not just a data grammar. And that is the strength of a grammar: a small set of rules generates an unbounded space of valid workflows, comprehensible to anyone who knows the rule.
The schema is the pipeline
The contrast is easiest to see in a picture: the same liquid-chromatography–mass-spectrometry (LC-MS) pipeline as a traditional relational database would model it, and then as a DataJoint schema.
A traditional database: the same pipeline as a relational schema (crow’s-foot notation). The entities as tables, each relationship named and carrying its crow’s-foot cardinality — the shape only, attributes left off for clarity (from the lcms-demo schema):
A computational database: the same pipeline as a DataJoint schema (equivalent to Figure 1 of Yatsenko & Nguyen 2026):
A traditional database records what happened. A computational database defines how it happens.
The ERD is accurate, and it is static. It shows the entities and how they relate — the shape of the data once it has landed — and nothing about how any of it came to be. It cannot say that ACQUISITION, MASS_ANALYSIS, and PEAK_DETECTION are produced by a computation rather than entered by hand.
The DataJoint schema is the same pipeline. It has the same entities and the same keys. Here, though, the schema specifies both: the data that exists, and the dependencies and code that bring it into existence. Tables are workflow steps. Foreign keys prescribe execution order. Every computed table declares its transformation in its own definition, versioned with your code. So the workflow is self-executing: change an input, and everything downstream recomputes, with full lineage preserved.
One formal system — the Relational Workflow Model — where structure, computation, and integrity are queryable and enforceable together. Reproducible by construction. Reusable by default.
A traditional database
A computational database (DataJoint)
Static — records relationships
Self-executing — manages data and runs computation
Describes the resting state
Specifies how each result is produced
The diagram is drawn about the data
The diagram is generated from the schema. It cannot drift from the pipeline that runs
The whole table in four lines
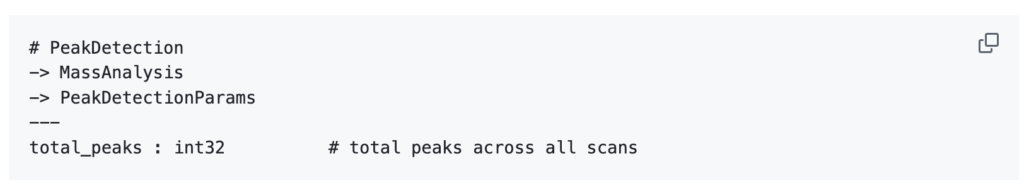
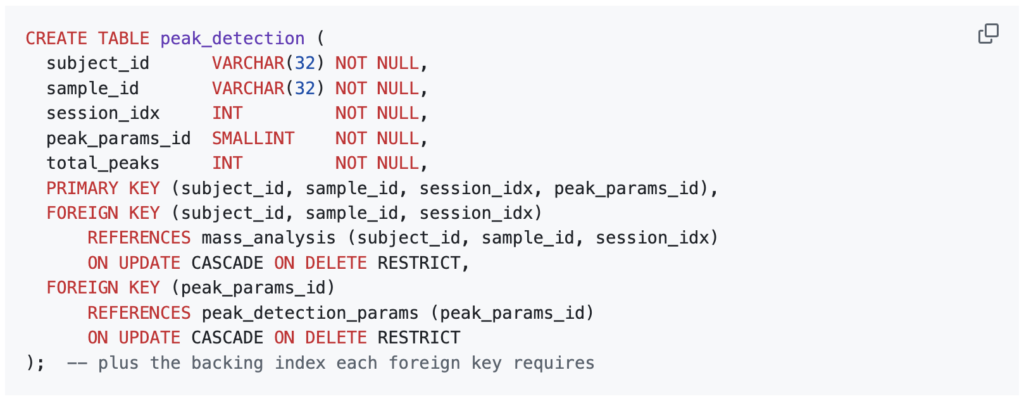
The whole-pipeline picture shows the shape. Zoom in on a single table and the same economy appears in its declaration. Take PeakDetection from the lcms-demo pipeline — the computed table where peaks are found in each spectrum under a chosen parameter set.
In DataJoint, the table definition is the whole spec, in four lines:
Two declarative lines — -> MassAnalysis and -> PeakDetectionParams — carry what the SQL spends most of its length spelling out: four inherited key columns, a four-part composite primary key, and two foreign-key constraints with their exact column tuples and referential actions. DataJoint says the same thing with far less to read. And it says the one thing the DDL cannot. Because PeakDetection is a computed table, its rows are produced by a make() method attached to this same definition, not entered by hand, and DDL has nowhere to put that. Attaching the transformation to the table itself is the Relational Workflow Model move formalized in DataJoint 2.0 — the subject of the next section.
Where the clarity comes from
The DataJoint form is shorter, but the point is not brevity. Each construct carries meaning the SQL has to rebuild by convention:
A foreign key carries the key, not just a pointer.-> MassAnalysisinherits MassAnalysis‘s entire primary key — subject_id, sample_id, session_idx — in a single line, as both the reference and part of this table’s own identity. You never retype an inherited column. The SQL names all four twice, once in the column list and again inside a constraint. A Computed table’s key is inherited from its dependencies in full.
The --- divider makes identity explicit. Everything above it is what identifies a detection run: which spectra, under which parameters. Everything below is dependent data (total_peaks). SQL relocates that distinction into a trailing PRIMARY KEY (...) clause read separately from the columns it governs.
A name means one thing, and it is enforced. Because keys propagate by name, subject_id refers to the same subject everywhere it appears. DataJoint’s semantic matching rejects any join between namesake attributes that do not share lineage. SQL’s natural join has no such guard: two unrelated id columns match silently.
The dependency is the execution order.-> MassAnalysis does not only add a constraint. It places PeakDetection downstream of MassAnalysis in the DAG, and dj.Computed together with its make() method declares that the table is produced from its parents. DDL describes storage. It says nothing about what fills the rows, or when.
You declare intent, not mechanism. The DataJoint definition states what the table is: a computed entity, identified by its two parents, holding a peak count. The SQL states how to store it: columns, types, keys, cascade rules. That gap, between a specification and its compiled form, is the same one this essay draws between the Relational Workflow Model and the Python that binds it.
The answer
The formal definition of scientific workflows — the typed entities, dependencies, and chains of data transformation that produce scientific results, in the same sense that Terraform is the formal specification of desired infrastructure state — is the Relational Workflow Model. It is the central contribution of DataJoint 2.0 (Yatsenko & Nguyen 2026) and it is independent of any particular binding, including the Python one most users see.
A Relational Workflow Model is a declarative description of five things:
The entities involved in the work: each a typed relation with an explicit primary key.
The dependencies between them: foreign keys forming a directed acyclic graph.
The transformation that produces each derived entity: a make() method on each Computed or Imported table, declaring how each tuple in the join of the upstream foreign-key parents becomes a downstream tuple.
The integrity constraints that must hold: referential, type, and uniqueness constraints, all enforced by the database itself rather than by convention.
The state of every derivation:Computed and Imported tables record, for every entity that should exist, whether it does, when it was produced, from what, and by whom.
That is a formal specification. Machines can parse it, tools can reason over it, and it is complete: from the model alone one can recover not only what the workflow is supposed to produce, but the rules for the transformations that produce it, the constraints they must respect, and the state of having (or not having) produced it.
Python is the binding. The binding is expressive and convenient, but it is not the spec. The spec lives one level below the binding, in the structure of the model itself. The grammar, semantics, query algebra, and machine-readable surface are written up in the new Schema as a Workflow Specification concept page.
In a follow-up conversation a few days later, the same architect saw the model demonstrated in a live workflow — every derivation row carrying the git hash of the code that produced it, the foreign-key DAG visible at a glance, every recomputation kicked off by deleting a row and letting the engine bring the world back into agreement with the schema. His phrase for what he was looking at: “You can now go build a dependency tree of provenance.” That is what the Relational Workflow Model produces, by construction. The model is not a new artifact. It is the formalization of what infrastructure architects already build for every other long-lived system, made explicit for the workflows that produce scientific results.
What “formal” gets us that the comparators do not
The architect’s instinct was that a formal language is what makes ecosystem interoperability possible. The question is whether scientific work fits in any of the existing languages.
It does not — at least, not without losing what makes the work scientific.
YAML, Terraform, Helm. These describe a desired static state: this is the network I want, this is the service I want to deploy, this is the cluster I want to stand up. They do not describe derivation. The derivation is delegated to an engine outside the spec — Terraform’s planner, Helm’s templating, Ansible’s runtime. That works for infrastructure because the desired state is the contract. For scientific work, the derivation is the contract. Outsourcing it to an engine breaks the spec at exactly the point where the spec needs to be authoritative.
Cedar. Cedar describes authorization policy: who may do what under what conditions. It is a fine formal language for one slice of a control plane: the gate-keeping slice. It does not describe the process the gates are gating.
CWL, Nextflow, Snakemake. These come closer. They were designed to describe scientific workflows. They do not, however, attach the transformation to the dependency edge as a single construct, and they do not unify data state with workflow state. The workflow lives in one file. The data lives somewhere else. The integrity of the join between them is the user’s responsibility. The structural side-by-side runs across nine concerns: data structure, types, foreign-key integrity, computation, execution order, provenance, drift detection, query interface, and retry. That comparison is laid out in the Comparison to Workflow Languages docs page.
We have tested this directly. A compiler we built takes a CWL project — using a 13-step GATK whole-genome-sequencing pipeline with four levels of nested sub-workflows as the worked example — and produces a self-contained DataJoint workflow: dj.Computed tables, explicit make() methods, and a foreign-key chain that mirrors the CWL step DAG. The same model also exports to Nextflow DSL2, one process per table, channel wiring mirroring the foreign-key chain. That is the demonstration that no information is locked in. The translation is asymmetric in exactly one place. DataJoint requires what CWL does not specify: entity names, typed primary keys, gather group keys. A short annotation YAML supplies that data structure. In operational terms, the Relational Workflow Model is a strict superset of the workflow-language category: anything CWL describes, the Relational Workflow Model describes — plus the data structure the science actually depends on.
A formal language is the precondition for interoperability. If the Relational Workflow Model is the spec for scientific workflows — the entities, dependencies, and chains of data transformation that produce scientific results — then:
An LLM can read it and answer questions about the work without first inferring what was done. The spec is the description.
A Unity-Catalog-style lineage view can attach to it and gain the transformation on each edge. The catalog records column-to-column dependencies; the Relational Workflow Model records what happened between them.
A simulation environment can run forward against it: change one node, propagate the effect, see what breaks before the change is committed. (Network operators have been doing this against network topologies for two decades. Scientific work deserves the same affordance.)
A policy engine like Cedar can attach to specific edges, gating consequential actions. The Relational Workflow Model says what the work is; Cedar says who is allowed to do it. They compose.
A new tool entering the ecosystem can speak the same language as the tools already there. That is the position the architect was pointing at — “that’s why Cedar took off — Amazon said, this is a really useful way to get people to come play our policy game.”
The Relational Workflow Model is the version of that play for scientific workflows. It is already specified. What remains is to set the model on the table next to Terraform and Cedar, so that the people who ask the formal-language question recognize the answer when they see it.
What adoption looks like
The architect’s harder question was the second one: how does a formal language actually become a standard? If interoperability is the prize, it is unclaimed until the language is adopted by an ecosystem of tools that did not originally know about it.
His own analogy was Network File System. NFS shipped as a simple, idempotent protocol in 1984. It was, in its first years, dismissed — files over a network, too slow, unreliable. Forty years later it is still in use. NetApp built a multibillion-dollar business on it, and a long tail of storage vendors followed. The protocol won not because it was clever, but because it was small enough to be implementable by anyone who needed it.
The Relational Workflow Model has the same shape. The construction is small: typed entities, an FK-directed acyclic graph, a transformation attached to each edge, a small set of integrity constraints, and the state of every derivation. The DataJoint 2.0 paper (Yatsenko & Nguyen 2026) specifies all five. The grammar is implementable in any host language with a relational substrate. Python is the binding we maintain, but it is not the only possible binding. The path to adoption is the same as NFS: make the spec simple enough that an instrument capture system, a regulatory submission packager, and a literature-evidence engine can each publish into or read from the model without rewriting their own data structures.
That is the work the formal language unlocks. The spec lives one level below the binding. The ecosystem can live one level above.
Closing
It was exactly the right question to ask: the kind worth answering with care, in writing, so the answer can be cited rather than restated each time.
The question was: what formal language describes a research workflow — the process that produces a scientific result?
The answer: the Relational Workflow Model. The schema is the specification. Tables are the typed entities, foreign keys are the dependency graph, make() methods on derived tables are the transformations, and integrity constraints and derivation state are part of the spec. Python is one binding; the spec does not depend on it. The model is defined in the DataJoint 2.0 paper (Yatsenko & Nguyen 2026); its grammar, semantics, and algebra are written up in the Schema as a Workflow Specification concept page; and its position among workflow languages is in the Comparison to Workflow Languages page.
This is also the exact meaning of the verb at the foundation of DataJoint’s capability roadmap: codify. To codify an experiment is to express it as a Relational Workflow Model — a formally defined, self-executing workflow whose integrity, provenance, and reproducibility hold by construction and stay free to evolve, so that people and their AI agents build on work that compounds instead of disappearing.
Nothing had to be invented to give this answer. The model has been built into DataJoint’s foundation from the start. Every DataJoint schema is already this specification. What the 2.0 paper (Yatsenko & Nguyen 2026) contributed was to articulate it succinctly and precisely: define the model, name it, and set it beside the other formal languages, so that the people who think in specifications can cite it, compare it, and build on it.
Imagine a brain in a jar. It's able to reason and process information but it can't do anything with that capability because it has no way to reach the real world. No hands to act, no eyes to gather new information, no way to know what happened after the last thing it thought.
AI agents have the same problem.
The conversation around agentic AI has focused almost entirely on the brain i.e., the model, the reasoning, the prompting, the orchestration logic. This all makes sense, since the brain is the exciting part. But agents don't operate in isolation. They operate inside systems, on real data and in real workflows. If those systems aren't built to support them, the agent's intelligence doesn't matter.
The body is the infrastructure. And most teams haven't built one.
What agents can't do on their own
In most organizations when agents get deployed into a workflow, the agent has no reliable way to know what the organization actually knows. This becomes tribal knowledge. That is, the information that lives in people's heads rather than in systems. Which file naming convention does the team actually follow?
What does "processed" mean in this pipeline? Why does this dataset have a duplicate column? This is the knowledge gap that makes agents frustrating in practice. Contrary to popular belief, it isn't the failure of the model itself but the environment the model is operating in. Agents can't read minds, they read whatever they can actually access. And most of the critical context about how a workflow operates isn't accessible to them.
The result: agents that hallucinate conventions they can't verify, miss dependencies that aren't documented and produce outputs that are plausible but inaccurate.
The first half of the body: context
If you want agents to work reliably, the first thing to build is a curated context layer. Importantly, not documentation for human readers. Documentation for agents. A corpus of information that is structured and current with machine-readable representations of how your system works including what data exists, how it was produced, what the rules are and what's allowed.
Think of this as a Context Harness. The idea is that agents shouldn't have to reconstruct the state of the world from scratch every time they act. They should be handed a harness, a structured interface to the knowledge they need, so they can spend their capability on the actual task instead of guessing at the environment.
The second half: determinism
If context tells agents what the world is, determinism ascertains what they can safely do in it.
This is where most infrastructure discussions stop short. They get context right but don't enforce any structure on the agent's actions. The agent has good information but no constraints on how it uses that information, which means a mistake can propagate silently, a failed step can be retried with side effects and there's no way to know what the agent actually did without going back through logs.
Here are five properties that make an agent's operating environment work the way it needs to:
These five properties don't constrain what agents can accomplish, they constrain how agents can fail. That becomes the difference between an agent that augments a workflow and one that destabilizes it.
What this looks like in practice
With DataJoint, scientists design the schema deliberately, and that design is instantiated directly from the code that governs the data. Every arrow in the pipeline diagram is a real enforced dependency. An agent reads the schema and knows the full structure of the scientific process, from raw acquisition through every derived analysis, without needing to ask anyone. It can't produce an orphaned result because the integrity constraints won't allow it. It can retry a failed computation because operations are reversible. It can report on the status of any step because the state is observable.
The schema isn't a record of the science. It is the science.
The inversion
When agents operate inside an environment with a real context harness and deterministic infrastructure, their actions are auditable. Every step is traceable. Every output has a provenance chain. The human scientist doesn't have to trust the agent blindly; they can inspect what it did and why.
This inverts the usual framing around AI and rigor. We tend to assume there's a tradeoff: move fast with AI or maintain discipline without it. But that tradeoff only exists when the infrastructure isn't there. Build the body first and the agent's productivity and the system's rigor compound in parallel.
AI increases research productivity and rigor not despite operational discipline. Because of it.
That's the thing most teams miss when they deploy agents and then wonder why results are inconsistent. They bought the brain. They didn't build the body.
Pharma R&D has spent the last three years quietly making AI load-bearing. Models now propose targets, score compounds, design assays, summarize literature, and increasingly draft sections of regulatory documents. The conversation has been about capability — what AI can do. The conversation we are not having, and need to, is about provenance — what the institution can prove about how it did it.
The argument is narrow and specific: scientific AI without deterministic provenance is not just messy. It is institutionally dangerous.
By deterministic provenance, I mean the ability to point at any AI-derived result — a hit list, a predicted structure, an annotated cohort, a generated experimental protocol — and reconstruct, bit-for-bit, the data, code, model version, parameters, random seeds, and upstream transformations that produced it. Not “logged somewhere.” Not “the analyst remembers.” Reproducible on demand, by someone other than the person who first ran it.
Most pharma AI today does not meet this bar. Notebooks reference data files whose schemas have since drifted. Foundation models are version-pinned on paper but rarely in practice. Pipelines stitch together SaaS APIs, internal scripts, and curated spreadsheets. The output looks crisp; the lineage is a smear.
This is fine when AI is a brainstorming partner. It becomes dangerous the moment AI output enters the institutional record — IND-enabling packages, IP filings, partnership data rooms, internal go/no-go decisions. Three failure modes follow.
First, regulatory exposure. FDA and EMA expectations are converging on reconstructable analyses. “Our model said so” is not a defense if the model, weights, and inputs cannot be reproduced. Sponsors who accelerate with AI but cannot defend the chain of derivation are accumulating a regulatory debt that comes due during inspection, not before.
Second, audit blindness when programs fail. Most clinical and preclinical programs fail. The institutional value of a failed program is the post-mortem — what did we believe, why did we believe it, where did the evidence break. When AI-derived intermediates cannot be reconstructed, the post-mortem cannot be performed honestly. The organization loses the ability to learn from its own failures, which is the most expensive form of institutional damage.
Third, decision velocity outrunning evidence integrity. AI compresses cycle times, which is the point. But the same compression means provenance debt accrues faster than humans can repair it. A team can make twelve AI-assisted decisions in the time it used to make one, with one-twelfth the lineage discipline. The danger is not that any one decision is wrong. It is that the organization can no longer tell which decisions rest on which evidence.
The fix is not more logging. Logging is observational and lossy. Deterministic provenance has to be a property of the system that produces results, not a record kept alongside it — data, code, and computation tracked in the same structure, with versioning and lineage that are queryable and reproducible. Designed in, not bolted on.
Leaders evaluating AI tooling should ask a single question of every vendor and every internal team: if a regulator, a partner, or a future post-mortem asks how this result was produced, can we rebuild it from if a regulator, a partner, or afuture post-mortem asks how this result was produced, can we rebuild it from first inputs, without depending on the person who ran it? If the honest answer is no, the institution is not adopting AI. It is borrowing against its own credibility.
The organizations that win the next decade of scientific AI will not be the ones with the largest models. They will be the ones whose AI outputs are still defensible three years after the analyst has left.
This is the conviction behind how we built the DataJoint platform: provenance as a first-class property of scientific computation, not alogbook kept beside it.
What if you could listen to hundreds of brain cells at once and still keep the data trustworthy and easy to share? This is what Neuropixels makes possible and how the community turns those signals into reliable results.
Quick hits: what Neuropixels make possible
Neuropixels are silicon probes that continuously detect tiny voltage changes from nearby neurons.Neuropixels probes, first released in 2017, set a new gold standardforlarge-scaleelectrophysiology [1]. The goal was simple to state and hard to do: record many single neurons in freely behaving animals with light, flexible hardware and many recording channels. Earlier probe stacks, such as passive NeuroNexus shanks with INTAN headstages, offered only tens of channels and relied on long analog cables that picked up electrical noise.
Neuropixels take a different path. Using complementary metal oxide semiconductor (CMOS) fabrication, the probe integrates amplification, multiplexing, and digitization on the device itself. Placing the electronics next to the recording sites shortens analog paths, reduces noise, and enables hundreds of addressable channels. This was not practical earlier because fabrication yields on long slender shanks were low, power and heat budgets were tight, and packaging had to remain biocompatible. Process advances and coordinated investment made it feasible. The result was a step change in experimental capability: stable, simultaneous recordings from hundreds of neurons across multiple brain regions in freely moving animals [1].
Adoption is broad. Our conservative estimate is that more than 850 laboratories have used Neuropixels since 2017*.
Who built it
The Neuropixels project is an international collaboration led by IMEC (Interuniversity Microelectronics Centre, Belgium) with partners including the Wellcome Trust, Howard Hughes Medical Institute (HHMI) Janelia Research Campus (Timothy Harris and colleagues), University College London (Matteo Carandini, Nicholas Steinmetz, and collaborators), the Allen Institute for Brain Science (Christof Koch and colleagues), Gatsby Charitable Foundation, the Sainsbury Wellcome Centre (John O’Keefe and colleagues), among others acknowledged in the original publications [1-3]. Their collaboration transformed what was once a technological aspiration into an accessible community resource. Neuropixels 2.0, co-developed with Cambridge NeuroTech, built upon this foundation with improved reusability and chronic stability [4,5].
From 1.0 to Opto: The Probe Line-Up
The development of Neuropixels has progressed through a series of significant releases, each enhancing its capabilities and resolution. This evolution highlights the ongoing advancements in neural recording technology.
Most Neuropixels models allow you to select up to 384 channels to record simultaneously from many more physical sites on the shank. The variants below differ mainly in site geometry, density, shank layout, and added capabilities (primate length, ultra-dense mapping, or built-in light for optogenetics).
Illustration showing the evolution of Neuropixels variants. Together, these releases extend Neuropixels from rodent studies to larger brains and from recording alone to tightly coupled recording and control. ‘Sites’ refer to individual electrode contact points, while ‘channels’ are the signals that can be read simultaneously.
Since its debut in 2017, the Neuropixels series has revolutionized neuroscience research. The original Neuropixels 1.0 featured 960 recording sites setting a new standard for high-density neural data collection in rodents. Building on that success, Neuropixels 2.0 arrived in 2021 with 1,280 recording sites per shank, ideal for chronic experiments with freely moving animals. By 2023, the lineup expanded further to include Neuropixels NHP for primates and clinical research. The same year, Neuropixels Ultra dramatically increased spatial resolution by pushing site density even higher for more precise spike detection and cell-type identification. Most exciting, the 2025 introduction of Neuropixels Opto combines electrophysiology with neurophotonics, enabling simultaneous electrical recordings and optical manipulation of neuronal activity through optogenetics.
These innovations represent a significant leap forward in neural research, evolving from small-scale rodent studies to detailed, large-scale analyses of the brain system. This includes ultra-high-resolution mapping and multimodal data integration, opening an exciting new chapter in neural exploration.
The Three-Step Guide to Choosing a Probe
Different probe designs serve different needs. Your choice should follow the question, species, surgery plan, recording duration, and budget.
Neuropixels integrates on-probe CMOS electronics with very high site counts per shank. Helpful for dense, stable, multi-region recordings in freely moving animals.
NeuroNexus offers a broad range of passive silicon probes in many geometries for acute and chronic in vivo recordings. Probes pair with external or headstage electronics, which keep them slender and flexible in configuration. Compared with Neuropixels, per-shank site counts are lower, with 32 sites per shank, and digitization occurs off-probe. Useful when you need custom layouts or thinner shanks.
INTAN Technologies offers low-noise amplification and digitization on the headstage used across many passive probes, including NeuroNexus and Cambridge NeuroTech. Adds headstage weight and analog cable length compared with on-probe designs. Flexible and cost-aware.
Cambridge NeuroTech focuses on chronic-focused silicon passive probes and implant hardware; partner on Neuropixels 2.0. Pairs with external electronics; their strengths include chronic implant hardware and diverse probe geometries. Strong for long-term stability and surgical accessories.
NeuroSeeker (EU-funded project) was an earlier initiative involving the Harris Lab at Janelia, IMEC, and UCL that advanced dense CMOS concepts that informed today’s designs.
TheMasmanidisLab at UCLA creates silicon probes with custom geometries, often distributed through collaborations with NeuroNexus or Cambridge NeuroTech. Good for specialised layouts.
DiagnosticBiochips builds high-density, small-form-factor probes designed for chronic rodent work. Emphasizes compact headstages and implant practicality.
How to choose:
Need highest per-shank site density and fewer external cables? Consider on-probe-CMOS designs.
Need unusual geometries or ultra-thin shanks? Consider passive silicon lines with external headstages.
Long-term chronic implant with specific surgical hardware? Choose vendors with mature chronic ecosystems (e.g., Cambridge NeuroTech, Diagnostic Biochips) and proven accessories.
From Acquisition to Sorting: The Open Toolchain at a Glance
Open tools made Neuropixels practical at scale:
SpikeGLX for high-performance data acquisition software optimized for Neuropixels. It enables stable, low-latency streaming of hundreds of channels. Developed by Bill Karsh (HHMI Janelia) and colleagues.
Open Ephys for a modular, open-source acquisition hardware and software for real-time electrophysiology. While compatible with multiple probes, it has been widely adopted for Neuropixels acquisition. Created by Josh Siegle (Allen Institute) and Jakob Voigts (MIT, Open Ephys company).
Kilosort for fast, GPU-based spike sorting tuned for dense data produced by Neuropixels. Developed by Marius Pachitariu and collaborators (originally at UCL and Janelia).
SpikeInterface for standardized preprocessing, spike sorting, validation, and comparison across multiple algorithms, including Kilosort. It integrates smoothly into Neuropixels workflows. Led by Alessio Buccino and Cyrille Rossant with an international community.
Together, these tools create an ecosystem that supports the acquisition, processing, and analysis of Neuropixels data with rigor and reproducibility. Their open-source nature has ensured broad adoption across labs worldwide, cementing Neuropixels as the foundation for modern systems neuroscience.
DataJoint in Action: What You Get
Running Neuropixels at scale is a data complexity problem, especially when done in multimodal experiments synchronizing other instruments.
DataJoint directly addresses the challenge of managing and analyzing terabyte-scale Neuropixels datasets in combination with other instruments as reproducible, cloud-ready workflows.
Ingests from SpikeGLX and Open Ephys automatically
runs spike sorting with Kilosort and other algorithms through SpikeInterface
Syncs and integrates with behavior, stimulation, and imaging
Writes results to Neurodata Without Borders (NWB) for sharing
Stores everything in structured, queryable databases for collaborative work.
Labs apply these approaches to deliver rigorous, reproducible analyses on large datasets. DataJoint helps you spend less time on infrastructure and more time on experiments.
Rigor and Transparency
The DataJoint Platform is a computational environment for scaling modern neuroscience — on the cloud or on premises in research labs. It automates steps from acquisition to sorting and analysis, scales to terabytes, integrates electrophysiology with multiple modalities, including behavior, imaging, and stimulation, and ships as open, community-validatedworkflows. FAIR practices and NWB export are built in. Additional capabilities include manual spike curation, advanced quality metrics for spikes and units, event-aligned analysis (e.g., PSTHs), and efficient compression of raw data for faster uploads.
Looking Ahead
Neuropixels continue to expand the boundaries of what is experimentally possible. As density and multimodal designs grow, workflows must keep pace. By working with the community and delivering scalable, cloud-based pipelines, DataJoint helps turn rich recordings into reliable, shareable science.
Upload. Analyze. Share. No local infrastructure required.
See you at SfN 2025! We’re excited to showcase our latest research. Don’t miss our nanosymposium presentation titled “Parametric Stimuli Reveal Functional Subcircuits in Visual Cortex.” Be sure to visit our poster, #PSTR198, where we’ll present “A Principled Framework for Compression and Standardization of Multiphoton Data.” Excited to connect with you there!
* Estimated from PubMed papers mentioning ‘Neuropixels’ since 2017, de-duplicated by institution and counting consortium papers once. This is a conservative lower bound.