Biomedical researchers struggle to reproduce their own work. In a 2024 survey of 1,630 of them, published in PLOS Biology, 72% said their field faces a reproducibility crisis. Of those who had tried to repeat one of their own studies, 43% could not.
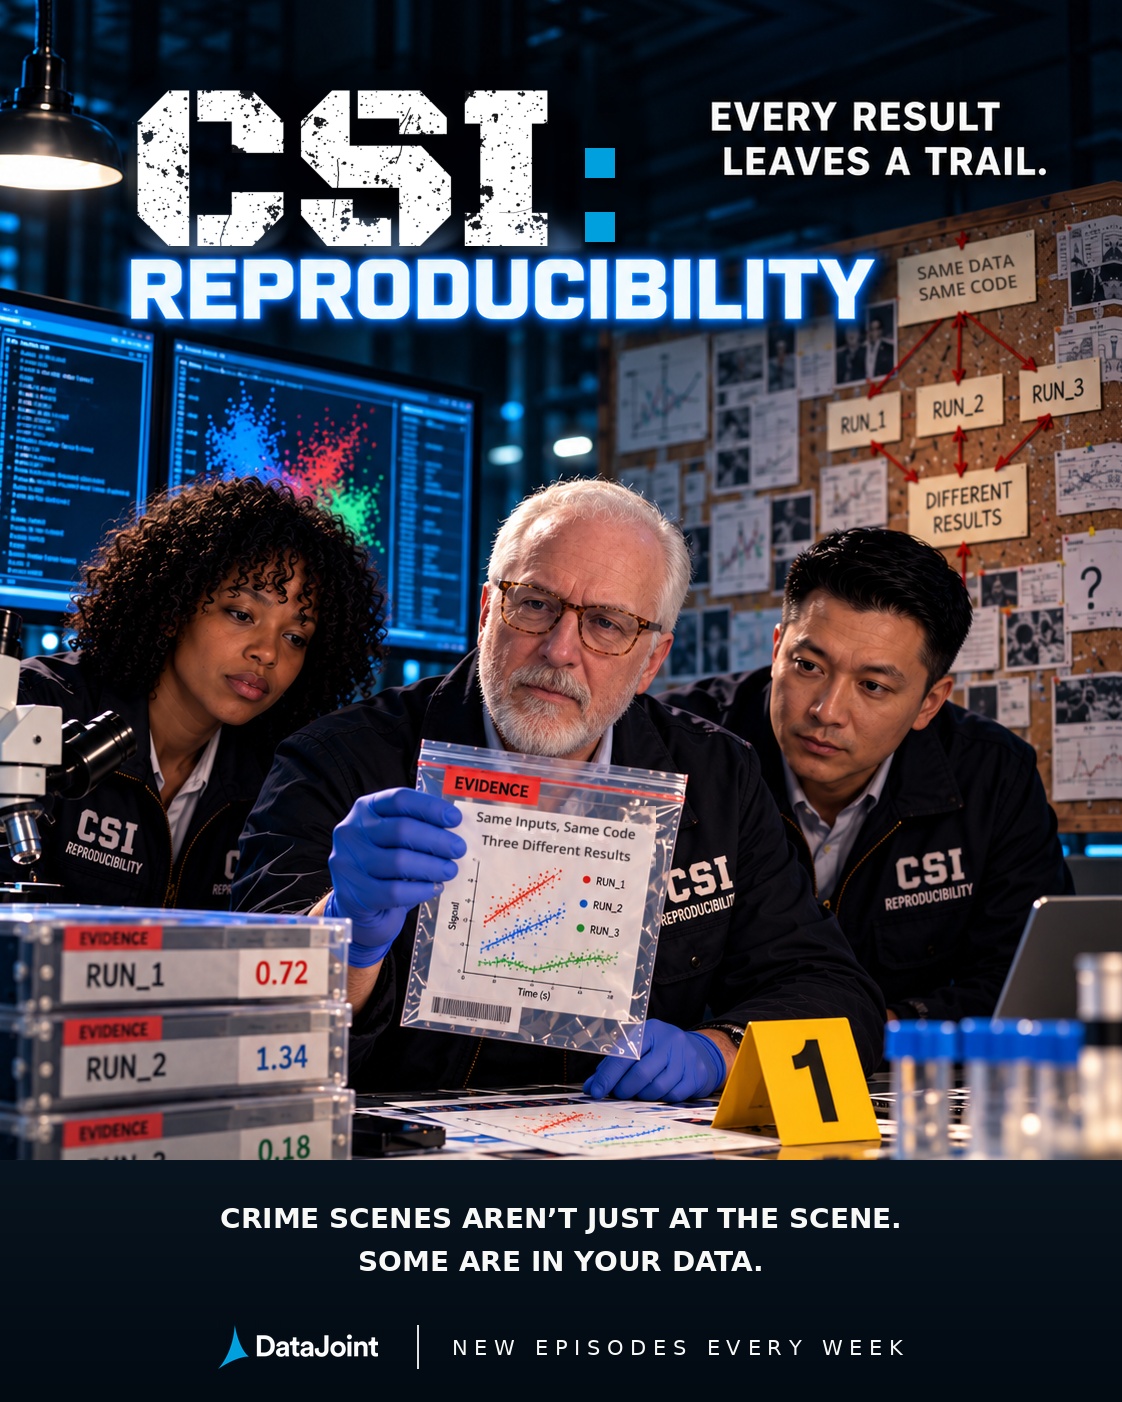
That last number is the stranger one. Reproducing someone else’s work means a different lab, different hands and different reagents. Reproducing your own work removes most of those differences, and it still fails. You run the same analysis a second time, get a different number, and no one can say why. The first run is already in the paper. Now you have two results and no way to tell which one is right.
This kind of failure is quieter than fraud and does more damage, because nothing flags it. A result you cannot account for looks the same as one you can, until someone asks you to account for it.
Why results diverge
A result can change between runs for reasons that never show up in the analysis: a parameter set by hand and never written down, a library that updated, a random seed, a different machine. A reviewer would not catch any of these, because the analysis looks the same both times.
So running it again does not settle anything. A third run may give a third number. Without a record of what each run used, you are comparing results you cannot explain.
The fix is a record of every run
It would be easy to claim that the same inputs always give the same answer. That would not be true. Much of what changes a result sits outside the code: software versions, seeds, hardware. No workflow can keep all of that fixed.
What a workflow can do is keep the record. In a grounded workflow, every run stores exactly what produced it: the inputs, the code version and the parameters. When two results differ, you put the two runs side by side and see what changed, such as a dependency or a parameter. You can also see which run matches the paper.
This is the lineage claim from the first episode, applied to a second run, and it holds without conditions. The number may still move. The record tells you why it moved and which version to trust.
Which one do you report?
The runs do not all have to agree, but when they disagree you need to be able to explain why. Then when a reviewer, an auditor or your future self asks which result is correct, the answer is in the record and not in someone’s memory.
A result you can account for is a result you can defend. A result you cannot account for is a liability wearing a lab coat.
With the record, you do not have to guess which result to trust.
Sources
Cobey, K. D., et al. (2024). Biomedical researchers’ perspectives on the reproducibility of research. PLOS Biology, 22(11), e3002870.
Trisovic, A., Lau, M. K., Pasquier, T., & Crosas, M. (2022). A large-scale study on research code quality and execution. Scientific Data, 9, 60.